An agile AI product team for Claude Code. You bring the idea. A Product Owner challenges it, an Engineering Manager plans it, the Developer builds it, a Reviewer audits the diff, a QA Tester clicks through your app in a real browser, and a Release Manager ships it — and nothing moves to the next phase until the previous gate is green.
aSPARK is a Claude Code plugin. No service, no account, no runtime: it is Markdown that installs into your project and leaves a reviewable paper trail in .spark/.
https://github.com/user-attachments/assets/714d2813-15d5-44f5-9644-dfaabf6524f9
The 100-second demo, narrated — one real 47-minute session, /spark to /go-live. Every time-lapse is marked. Also on aspark.lottes.dev.
See it work
One command runs the whole loop. It stops at every gate and shows you the artifact before moving on — you stay the decision maker.
You:     /spark I want a dashboard where users see their weekly stats

Claude:  [Product Owner]  Challenges the idea, asks what "weekly" means for a user
                          in another timezone, writes spec.md with US-1…US-3 and
                          testable acceptance criteria. → Gate: you approve the spec.
         [Designer]       Flags an empty-state gap and a contrast risk in the spec.
         [Eng. Manager]   Decides the architecture, cuts 6 tasks into plan.md, each
                          mapped to a story. → Gate: you approve the plan.
         [Developer]      Builds task by task. No scope creep — the plan is the fence.
         [Reviewer]       Reads the diff, finds an off-by-one in the week boundary,
                          files F1 (Major) in review.md, fixes it, re-checks.
         [QA Tester]      Opens http://localhost:3000, verifies AC-1.1…AC-3.2 in the
                          browser, files a bug where the chart never loads on mobile.
                          → Gate: back to the Developer, then QA again.
         [Release Mgr]    Changelog, tag, PR. → Gate: your explicit go.
What lands in your repo:
.spark/
├── constitution.md         ← project-wide ground rules, set once with /charter
└── weekly-stats-dashboard/
    ├── spec.md             ← stories US-n, acceptance criteria AC-n.m, NFRs
    ├── plan.md             ← architecture decision, ordered tasks T1…Tn
    ├── review.md           ← findings F1…Fn with severity and location
    ├── qa.md               ← every AC and NFR verified, pass/fail, in the browser
    └── release.md          ← changelog, version, what was learned
Requirements carry stable IDs from the spec all the way through: the plan cites which AC each task covers, the review traces each Must AC to code, and QA verifies it under the same ID. Nothing silently falls out of the chain.
Two real, complete examples you can read today:
- steamcore — an ESP32 arcade console built from scratch with aSPARK: 13 features, each with its full spec → plan → review → QA → release trail under
.spark/. Start withhighscore-system. It has no browser surface, so it also shows the declared substitute-QA path. - this repository — aSPARK is built with aSPARK; its own
.spark/folder is the trail of alibrary-type project.
Install
Requirements: Claude Code and Git. For /demo-day you also need a browser integration (Claude in Chrome, or a Playwright / Chrome DevTools MCP server), unless your project has no browser surface and /charter declares a substitute QA method.
Inside an interactive claude session:
/plugin marketplace add a-lottes/aSPARK
/plugin install aspark@aspark
Then restart Claude Code. /plugin should list aspark as enabled. From a plain shell or CI, the same two steps are claude plugin marketplace add a-lottes/aSPARK and claude plugin install aspark@aspark. To hack on aSPARK itself: claude --plugin-dir /path/to/aSPARK.
Start here: on a new project, empty or already full of code, run /charter first. On an empty repo it asks a handful of hard product questions and ends by offering /story-time with the first slice named. On an existing codebase it reads the repo and writes down what it found, for you to correct once. Either way the team stops re-deriving what your project is on every feature. You can skip it, but /spark and /next-steps will point you here first.
The loop
Every feature travels through five phases — Specify, Plan, Act, Review, Keep — and may only move forward when the previous phase's gate is green.
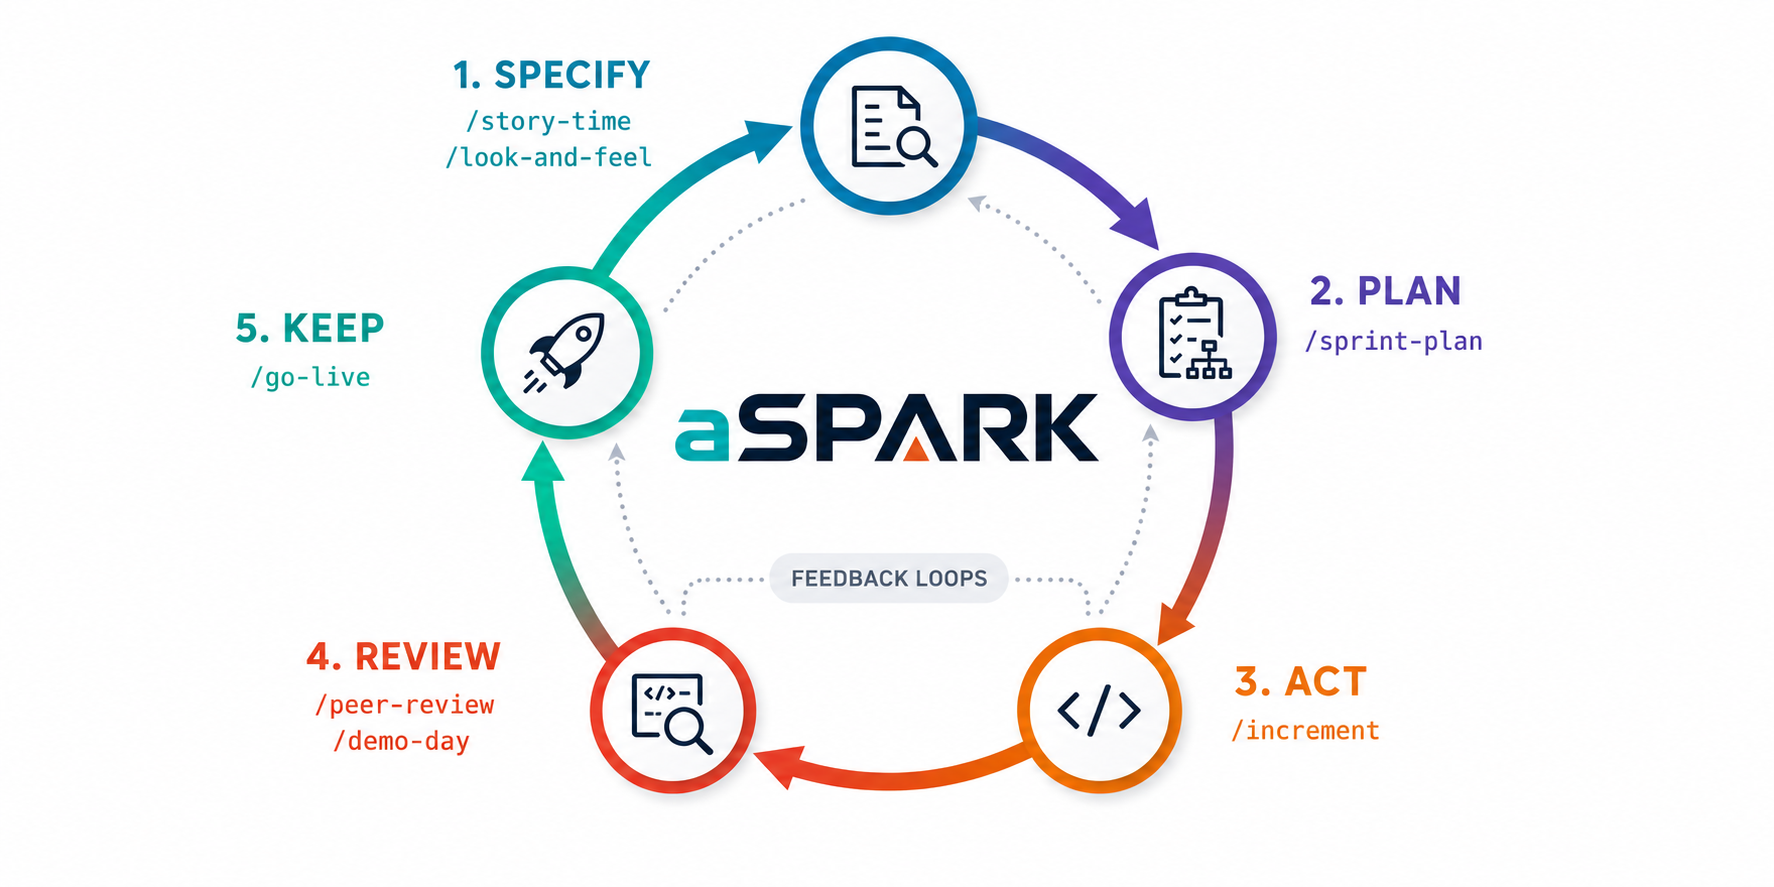
| Phase | What happens | Gate to pass |
|---|---|---|
| Specify | The idea is challenged, clarified, turned into user stories with acceptance criteria and NFRs, and design-checked. | Spec approved by you. |
| Plan | Architecture decided, work cut into ordered tasks. | Plan approved by you; every task maps to a story. |
| Act | The increment is built, strictly following the plan. | All tasks done, build and tests green. |
| Review | Code review by a senior eye, then hands-on QA in a real browser. | No blocking findings, every AC verified. |
| Keep | Released, or handed off as a PR in a PR-mode project. Learnings recorded. | Released and documented. |
Review or QA findings go back to the Developer and the phase re-runs. After three failed rounds of the same phase the loop stops and asks you whether the plan or the spec is wrong, instead of grinding.
The team
| Command | Role | What they do |
|---|---|---|
/charter |
📜 Facilitator | Sets the project's standing principles and profile in constitution.md, once. |
/next-steps |
🧭 Product Owner | No idea in hand? Surveys the project, triages open tickets, finds ticket gaps and proposes one typed next step (foundation first on a new project). Ticket triage is best effort, see docs/status.md. |
/backlog |
🧭 Product Owner | Documents but no backlog? Reads docs/, proposes an ordered list you edit, then files it as GitHub issues /story-time <n> can import. |
/story-time |
🧭 Product Owner | Interrogates your idea, no yes-man. Writes stories, ACs and NFRs into spec.md. Pass a GitHub issue number (/story-time 42) to start from that ticket instead of retyping it. |
/look-and-feel |
🎨 Designer | Usability heuristics, consistency, accessibility. Adds a design section to the spec. |
/sprint-plan |
🏗️ Engineering Manager | Locks the architecture, cuts ordered tasks into plan.md. |
/increment |
💻 Developer | Builds the increment following the plan. Also runs fix rounds. |
/peer-review |
🔍 Reviewer | Reviews the diff with a staff-engineer eye, writes review.md. |
/demo-day |
🧪 QA Tester | Clicks through the running app in a real browser, verifies every AC, writes qa.md. |
/go-live |
🚀 Release Manager | Pre-flight, changelog, tag or PR. Refuses while QA has open blockers. Opt-in: posts one status comment to the feature's GitHub issue. |
/spark |
🤹 Orchestrator | Runs the whole loop, or resumes a feature from wherever it stands. |
Each ceremony can also be run on its own. The artifacts on disk are the state, so you can /clear after a heavy phase and pick the loop back up with /spark.
The loop adapts to what you're building
/charter records what kind of software this is (website, web-app, api, cli, library) and what it does with data (auth, payments, PII, database, multiple languages, accessibility mandate). That switches on matching lenses: extra checks the existing team applies only where they apply. A public website gets SEO and Core Web Vitals in QA. An API gets error-envelope and versioning checks in review. A project that handles payments gets the security lens through every phase. Ten lenses are written; the tenth, observability (diagnosability of a running api), has only been dry-run, not exercised on a real project; adding one is a new file in lenses/. Without a constitution, no lens fires.
Gate hardening: searched, no rebuttal rows shipped
The gates are prompt-enforced: an agent can reason its way past one, and Core, being Markdown with no runtime, cannot stop it. Code-level enforcement is the optional sibling aspark-guard's concern.
- Rebuttal rows were to go only where an evasion was actually recorded. A search of this repo's own 51 review, QA and evidence files (
evidence.md) found one recorded gate evasion where the bar was two at the same gate, so no rows shipped at any gate; no skill gained a row. - The grounding is in-repo trails, not field reports. The search was fixed-term, not a census. Effectiveness is unmeasured, and whether a row would fire cannot be tested in Core.
- Stricter verdict rules now ship separately (next section). A second, independent reviewer is not built (re-open only on a new argument or observation, such as a recorded single-reviewer miss).
Stricter verdicts: the anti-generosity standard (always on)
Every /peer-review and /demo-day run hands the Reviewer or QA Tester standards/anti-generosity.md; there is no opt-in or opt-out, and the report should name it as applied.
- This changes verdicts for already-installed projects. Each item is PASS or FAIL with the observable that decided it; a check only read, simulated or partly run is recorded
⚠ not-verified-live, never as a pass; the report states which evaluation mode was available; a finding is not downgraded without a cited reason. Expect more⚠cells and stricter verdicts than before. - Prompt material only, effect unmeasured. It makes a strict verdict likely, not certain; the skill tells you if a report does not name the standard. The live dry runs could not be performed in the build environment, so no observed rate is claimed (
evidence.md). Code enforcement isaspark-guard's concern; a second, independent reviewer is not built. - Silent in every other ceremony;
/go-liveis unaffected.
Campaigns: one measurable goal instead of one story (experimental)
A campaign is a second way of working, next to the feature loop: one machine-decidable goal, one budget, run in iterations until the goal is reached or a stop rule halts it. You approve the goal; the agent only iterates inside it. One kind ships today, migration-campaign: a migration in reversible slices, with a fresh Parity Verifier per slice. A new kind is one file in campaigns/, the same way a lens is.
What this is, plainly:
- The need is anticipated, not observed, and effectiveness is unmeasured. Only one kind exists.
- Budgets and stop rules are followed by the agent, not enforced by Core. Core is Markdown with no runtime; enforcement is
aspark-guard's concern, and without it nothing changes and nothing is reported. /campaign <name> [kind]starts a campaign: it reads the plugin's kinds itself, asks only what the kind leaves open and writes a draft.spark/campaigns/<name>/campaign.md, then stops. It is instructed never to approve, run or commit, and to refuse an undecidable goal, several goals, an existing name or a goal that fits no kind. That is prompt-followed, measured as best-effort, never a guarantee (campaigns/README.md). With one kind it serves migrations only. The old hand-start (naming the plugin folder in a prompt) still works.- Running a campaign is still hand-run: you name the instance. The loop ceremonies have no campaign logic yet, so nothing routes to one on its own, and the migration kind's standing rule for ordinary features is inert until routing ships. Project-local kinds are not built either: only the plugin's own kinds are read.
- A repo without
.spark/campaigns/sees no difference.
Project Status
In real use, not an experiment. aSPARK runs on the author's projects and on a growing number of others, most of them closed source. In the two weeks to 29 Sep 2026 the repository was cloned from 484 unique sources, and even on the quietest days 26 to 30 of them turned up (a plugin install clones it). Outside users file issues and send pull requests that come out of their own loops; one of them contributed a third machine's metrics report. The numbers, their source and what they do not show: docs/status.md § Adoption.
The loop itself is measured, not claimed: 77 features across three machines, with 429 role-agent runs and 377 human gate decisions. Every figure is re-derivable from the committed reports in docs/reports/ with standard-library Python, see docs/metrics.md.
What one loop costs. One complete run — todo-filter-bar, /spark to released tag, 47 minutes, 29 acceptance criteria — took 42,307,448 tokens, which is $35.52 at Opus 5 list prices. 96.3% of those are cache reads: without prompt caching the same loop would cost $217.37. The per-role breakdown, the method and what the figure does not say are in what a full loop costs — it is one data point on one model at list prices, not a subscription bill.
Most use beyond the author's projects is on closed-source code, so it can't be linked. The aSPARK reads series runs aSPARK on well-known open-source code and publishes every source. If you run aSPARK on anything real, a field report is worth more than a patch, especially when it went badly. Per-capability proof state, every partial and why: docs/status.md. What ships next: ROADMAP.md.
Optional Tools
Core has no dependencies. Two optional companions hook into the loop if you install them; without them the loop behaves exactly as described above, no warning, no mention.
- aspark-guard — enforces the gates in code, outside the model: denies a
.spark/write that violates a phase precondition and records every write with its hash./plugin install aspark-guard@aspark. - aspark-graph — a deterministic graph over your
.spark/artifacts and code, used by/sprint-plan,/peer-reviewand/demo-dayto scope work.pip install aspark-graph.
Two further siblings, aspark-insights and aspark-policy, do not touch the loop today. The whole family, with what each one's evidence does and does not cover: docs/family.md. Site: aspark.lottes.dev.
Going deeper
docs/workflow.md— how artifacts hand over, what each gate checks, who may decide what.docs/repo-layout.md— whatagents/,skills/,templates/,lenses/,campaigns/andtools/are, and the reading order for newcomers.CONTRIBUTING.md— how to add a lens, campaign kind, skill or agent without breaking the contract.CLAUDE.md— working habits kept across loops.
License
MIT © 2026 Andreas Lottes