Turn any webpage into clean Markdown an AI agent can actually use.
distill is a local CLI (and MCP server) that takes a URL or HTML file and
returns Markdown with:
- nav / ads / footers stripped
- tables, code blocks, and lists kept intact
- relative links resolved to absolute URLs
- title / author / date in a YAML frontmatter block
No cloud API. No per-page cost. Same input → same Markdown every time.
distill https://en.wikipedia.org/wiki/Markdown
# → clean Markdown on stdout
What it is (in one minute)
| Input | A URL, an HTML file, or HTML on stdin |
| Output | Clean Markdown (+ optional YAML metadata) |
| Where it runs | On your machine — nothing is sent to a cloud service |
| Who it's for | Agents and developers who need docs, tables, and product pages — not just news articles |
Most “reader mode” tools were built for blog posts. Agents usually need API docs, pricing tables, forum threads, and reference pages. Distill is built for that: structural fidelity first, then speed and privacy.
Ways to use it
- CLI —
distill <url>in a shell or script - MCP server — tools
distill_url,distill_urls,distill_htmlfor local agents (Claude Code, etc.)
Published as
distill-mdon crates.io / npm (the namedistillis taken). The installed commands are stilldistillanddistill-mcp.
Install
# Agents (MCP) — no install, always latest
npx -y -p distill-md distill-mcp

# Shell installer (macOS / Linux) — prebuilt binary
curl -LsSf https://github.com/gokulnair2001/distill/releases/latest/download/distill-md-installer.sh | sh

# Rust toolchain
cargo binstall distill-md      # prebuilt
cargo install distill-md       # from source

# From this repo
cargo build --release --features mcp
# → ./target/release/distill  and  ./target/release/distill-mcp
Prebuilt binaries for macOS (arm64/x64), Linux (arm64/x64), and Windows (x64) ship with every GitHub Release. See RELEASING.md for how releases are cut.
Usage
# URL
distill https://en.wikipedia.org/wiki/Markdown

# Local HTML file
distill page.html

# Stdin
curl -s https://example.com | distill -

# Several inputs → one .md file each (-o is a directory)
distill https://a.com https://b.com page.html -o out/
# → out/a.com.md, out/b.com.md, out/page.md
# A failing input is reported and skipped; the rest still write.

# Common flags
distill <url> \
  --render auto \      # JS rendering: never | auto | always (default: auto)
  --no-frontmatter \   # omit YAML metadata
  --no-links \         # keep link text only
  --no-images \        # drop images
  --raw \              # skip main-content extraction (convert whole page)
  --base <url> \       # base for resolving relative links
  -o out.md            # write to a file (or a directory, for multiple inputs)

# Agent-ready JSON (opt-in): sectioned Markdown + RAG chunks + schema
distill <url> --agent-ready        # long form
distill <url> --ars                # alias
distill <url> -A -o page.json      # short form
Agent-ready output (--agent-ready / --ars / -A)
Default output stays plain Markdown. With --agent-ready, Distill emits JSON
with three layers agents can use without re-parsing a flat blob:
| Field | What it is |
|---|---|
sectioned_markdown |
Normalized headings + a Contents outline |
chunks |
RAG units: {id, heading, level, text, source} |
schema |
Structured extract: meta, outline, links, tables, code blocks |
Deterministic and local — no LLM. Same extract/convert pipeline; only the final shape changes.
JavaScript rendering
Some sites (SPAs) only fill in content after JavaScript runs. Over plain HTTP you get an empty shell.
Distill is static-first:
--render |
Behavior |
|---|---|
auto (default) |
Fetch HTML normally; start a headless browser only if the page looks under-rendered |
always |
Always use the browser |
never |
Never use the browser (fastest; fails on JS-only pages) |
Needs an installed Chrome / Chromium / Brave / Edge. Set DISTILL_CHROME to
point at a specific binary. If none is found, distill falls back to static HTML.
Most docs sites (VitePress, Next.js SSG, etc.) already ship full HTML — rendering them changes nothing. The browser path only helps genuinely client-rendered pages.
How it works
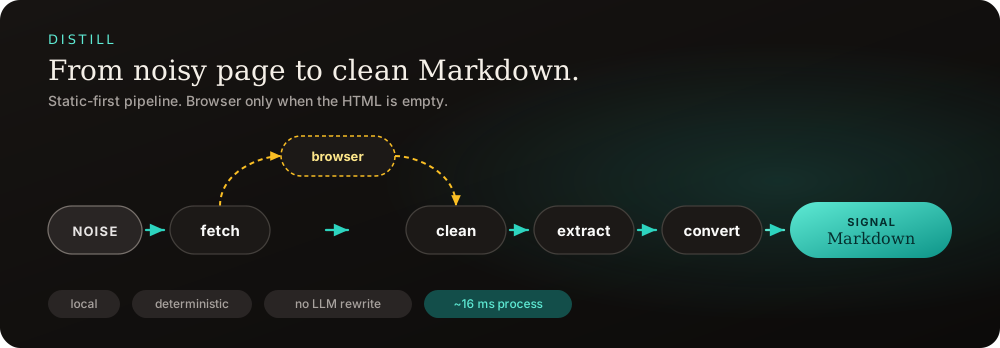
- fetch — Download the page with browser-like headers; follow redirects; decode gzip/brotli and character encodings.
- render? — Optional headless Chrome, only when the static HTML looks empty or extraction finds almost no content.
- metadata — Pull title / author / date / lang / canonical from
<head>. - clean — Remove scripts, nav, footer, aside, ads, and other boilerplate (matched by tag and by class/id, with care not to delete real content like forum threads).
- extract — Score text blocks (Readability-style) and pick the main content region; merge nearby siblings when the page splits content across wrappers.
- convert — Walk the DOM and emit Markdown: real tables, fenced code with language hints, nested lists, blockquotes, absolute links and images.
Why it's fast
Most of the speed comes from avoiding work, not micro-optimizations.
Process-only median on cached HTML: ~16 ms/page (see Benchmarks). Network time dominates end-to-end; that number is the stable, network-free figure.
Key terms
| Term | Meaning |
|---|---|
| Static fetch | Download HTML over HTTP as-is — no browser, no JavaScript |
| SPA / client-rendered | Page whose content only appears after JS runs (often an empty shell at first) |
| Headless Chrome | Chrome with no visible window; used only to run JS and dump the final HTML |
| DOM | The tree of HTML elements after parsing (div, p, table, …) |
| Deterministic | Same input always produces byte-identical Markdown |
| Process time | Time spent converting already-downloaded HTML (no network) |
Four reasons
-
Static-first — Docs and Wikipedia-style pages already have content in the HTML. Distill uses that and skips the browser. Chrome runs only when the body looks empty, SPA mounts (
#root,#app, …) are empty, or extraction yields almost nothing (under 200 characters of main content). -
Rust + lean deps — Native binary, small HTML parser (
kuchikiki), blocking HTTP client. No LLM in the convert path. Release builds use LTO and strip. -
Cheap JS when needed — Shells out to an installed Chrome with
--dump-domand a virtual-time budget. No heavy browser-automation library inside the binary. Rendered HTML then reuses the same clean → extract → convert path. -
One deterministic pass — No model, no sampling, no “rewrite for quality.” One pipeline, same output every time.
In one line: skip the browser whenever possible; only pay for Chrome on real JS-heavy pages.
MCP server
Expose distill as tools any local agent can call (Model Context Protocol, over stdio):
| Tool | What it does |
|---|---|
distill_url |
Fetch one URL and convert it (SSRF-guarded) |
distill_urls |
Fetch up to 20 URLs (4 at a time); per-URL ok/error blocks |
distill_html |
Convert HTML you already have — no network |
Same knobs as the CLI (include_links, include_images, frontmatter, raw,
base, agent_ready; URL tools also take render).
# Register with Claude Code (published package)
claude mcp add distill -- npx -y -p distill-md distill-mcp

# Or a local build
cargo build --release --features mcp
claude mcp add distill -- /absolute/path/to/target/release/distill-mcp
Or in mcp.json:
{
  "mcpServers": {
    "distill": {
      "command": "npx",
      "args": ["-y", "-p", "distill-md", "distill-mcp"]
    }
  }
}
SSRF guard
Agents can pass any URL into distill_url. By default, requests to non-public
addresses are refused — loopback, private ranges, link-local (including the
169.254.169.254 cloud metadata endpoint), and IPv6 equivalents — on the
initial URL and every redirect / meta-refresh hop.
To allow a local or internal host:
DISTILL_ALLOW_PRIVATE_HOSTS=1 distill http://localhost:3000
Same env var for CLI and MCP.
Benchmarks
50-URL corpus (bench/corpus.jsonl): articles, docs, product pages, forums,
table-heavy pages, and SPAs. Measured 2026-08-09 against Jina Reader,
Firecrawl, trafilatura, readability-lxml, and markitdown.
Reproduce with bench/.
| metric | distill |
|---|---|
| coverage | 92% usable output |
| process time (median, network-free) | ~16 ms/page |
| output size | ~15.3k tokens/page (avg) |
| deterministic | yes |
Structural preservation (micro-average kept ÷ source; tables and code blocks are the high-signal features — link/heading ratios often just mean “kept more nav junk”):
| tool | tables | code blocks | coverage | local? |
|---|---|---|---|---|
| distill | 0.62 | 0.94 | 92% | yes |
| jina | 0.27 | 0.17 | 100%* | no (cloud) |
| trafilatura | 0.18 | 0.69 | 92% | yes |
| readability | 0.00 | 0.00 | 80% | yes |
| markitdown | 0.57 | 0.68 | 66% | yes |
* Jina’s coverage is real, but its link/heading/image keep rates are inflated by boilerplate. On tables and code blocks it is the weakest of the group.
Known limitation: a few heavy client-rendered docs sites do not finish populating within the current headless-Chrome time budget. Bug history and methodology notes live in bench/README.md.
Roadmap
- JS rendering — static-first, Chrome only when needed
- Benchmark harness vs cloud and local alternatives (
bench/) - MCP server (
distill_url/distill_urls/distill_html, SSRF-guarded) - Agent-ready structure — opt-in
--agent-ready/--ars(sectioned MD + RAG chunks + schema) - Page-type awareness — distinct strategies for docs / listings / tables
- More structural fidelity — colspan/rowspan,
<picture>/srcset, … - Schema-guided extraction — caller-supplied JSON schema (LLM or rules)
Development
cargo test                     # unit + integration tests
cargo test --features mcp      # include the MCP server
cargo build --release
For LLM-facing checks of Distill’s Markdown / --agent-ready JSON on a fixed
12-URL corpus, see bench/llm_suite/
(python3 bench/llm_suite/generate.py → gitignored out/).
License
GNU General Public License v3.0 or later — see LICENSE.