JevBench — Benchmark for AI Decision Models
Jev is TypeSafe AI's decision model; JevBench also evaluates Jev-compatible systems. The canonical JevBench board is https://benchmarkheaven.com/jev-models.
Current results and scoring
JevBench by Benchmark Heaven is a benchmark for AI decision models, including Jev-compatible systems. It measures typed decision accuracy, probability calibration, latency and cost. Maintained by Benchmark Heaven, independently of TypeSafe AI.
Current open-weights board · Hosted API board · Methodology · Data card · Benchmark comparison
Published release: v1.6.1, initially published 2026-10-06. Version permalink. Published addenda: a6 (2026-10-07), a7 (2026-10-07), a8 (2026-10-07), a11 (2026-10-08), a12 (2026-10-08); amended through 2026-10-08. Latest row measurement: 2026-10-07. This list includes additions embedded in the results artifact; method amendments and board revisions are listed separately on the versioned board. Cite source_sha256 5cd8c1332226ea9c179883d2285c0d8b8cc593ae38f2645197364a7ddd9c83c1 for the exact published bytes. The live board may also include later dated API reruns and presentation revisions.
Capability Score: Arithmetic mean of Intelligence and Calibration; ranked models within both official caps. Headline on the open-weights board. Cost cap: USD 0.0646 per 1,000 decisions; adjusted median-latency cap: 1.23 seconds.
Composite Score: Weighted harmonic mean of Intelligence, Calibration, Speed and Cost, multiplied by squared penalties when Intelligence is below its configured floor, or Speed or Cost is below 50. Equal 25% weights do not mean an arithmetic average. Option A: weights Calibration 25%, Cost 25%, Intelligence 25%, Speed 25%; Intelligence floor 50. Composite is secondary on open weights and leads the hosted API board.
Authoritative release manifest · Own results JSON · Own results CSV. Missing measurements are null, never zero. No third-party benchmark numbers are included.
Limitations: finite task coverage; sealed inputs prevent complete independent reruns; hosted endpoint versions can be opaque; cost is modeled from the published basis and latency depends on the runtime and measurement location. Training on the public split must be disclosed. A leaderboard score does not establish reliability on your workload.
Name disambiguation: this is JevBench by Benchmark Heaven at benchmarkheaven.com. The metamorphic coherence benchmark is a separate project; its consistency scores measure a different property.
Historical releases retain their original scoring definitions and measurement sets. Do not compare scores across method versions as if they were the same experiment.
Historical releases
Combination experiments (confidence cascades, committees, and real-sample best-of-n) are reported in RESULTS-COMBINATIONS.md. None changed the ranked board.
v1.5 method record
JevBench v1.5's frozen method and its disclosed release addenda are available in the v1.5 method index. It links the unchanged frozen method, every v1.5 addendum, and a SHA-256 manifest.
v1.4.2.2: Imajev-4B leads; Plumb-4B is #2 (historical release)
Live board · v1.4.2.2 release notes · v1.4 method · aggregate results · changelog
The v1.4.2 scorer is unchanged. v1.4.2.2 adds Imajev-4B, measured on the full v1.4 protocol with one rotation and calibration.json, to the exact v1.4.2.1 result. The board has 95 systems, 91 ranked; prior measurement and score fields remain unchanged, with ranks moving only where the added row changes the order. Only aggregate sealed statistics are published.
| Rank | System | JevBench Score |
|---|---|---|
| 1 | Imajev-4B | 67.37 |
| 2 | Plumb-4B (crh225, JevK5 v0.2 + LoRA) | 65.84 |
| 3 | decider-4b v2 (Mapika) | 64.13 |
| 4 | Jev 1.13.0 (TypeSafe AI) | 63.29 |
| 5 | JevK5 v0.2.0 | 62.04 |
Imajev-4B's estimated Cost uses the public DeepInfra Qwen/Qwen3.5-4B reference price and zero generated output tokens. It is a model-price estimate, not a GPU bill.
v1.4.2.1: Plumb-4B added (previous release)
Live board · v1.4.2.1 release notes · v1.4 method · aggregate results · changelog
The official score blends 20% chance-corrected Intelligence from 308 fresh sealed decisions with 80% of the v1.3.0 Intelligence axis. Calibration is blended toward the sealed-inclusive measurement. The four axes use an equal-weight harmonic mean. A public-to-sealed accuracy gap above 25 percentage points reduces Intelligence; the existing low-Intelligence penalty remains, and Speed and Cost each receive a quadratic gate below 50.
| Rank | System | JevBench Score |
|---|---|---|
| 1 | Plumb-4B (crh225, JevK5 v0.2 + LoRA) | 65.84 |
| 2 | decider-4b v2 (Mapika) | 64.13 |
| 3 | Jev 1.13.0 (TypeSafe AI) | 63.29 |
| 4 | JevK5 v0.2.0 | 62.04 |
| 5 | Cygnet (blockbrain, frozen Gemma-4-12B-it) | 61.76 |
Plumb-4B takes the highest equal-weight composite. Jev 1.13.0 out-reasons decider-4b v2 (Intelligence 53.1 vs 49.4) and is better calibrated; decider-4b v2 leads on speed and cost. JevBench weighs the four axes equally; sort by Intelligence for raw reasoning.
v1.4.2.1 adds Plumb-4B to the live v1.4.2 baseline: 94 systems, 90 ranked. The v1.4.2 scorer and prior measurements are unchanged; ranks move only where the added row changes the order. Plumb's estimated Cost uses the bookable EmpirioLabs Qwen3.5-4B input rate of $0.04/M, not a GPU bill. Only aggregates are published for the sealed items. Rows with an API flag identify operator endpoints that received item text without answer keys. The public half can be trained on or selected against, so the held-out private part will need to evolve as the field changes.
v1.4.2: eleven new systems and swanOne's sealed run
v1.4.2 release notes · aggregate results
v1.4.1: six completed additions to the v1.4 board
v1.4.1 release notes · aggregate results. The previous top five was Jev 1.13.0 (63.29), JevK5 v0.2.0 (62.04), Hopper (59.43), Winnow-12B Q8 (55.58) and reflex 4B (53.99).
v1.3.0: previous scoring release
Results -> RESULTS-v1.2.md · artifact results/v1.2/jevbench-v1.2-results.json ·
interactive: benchmarkheaven.com/jev-models · how the hard tier was made: datasets/HARD-TIER.md
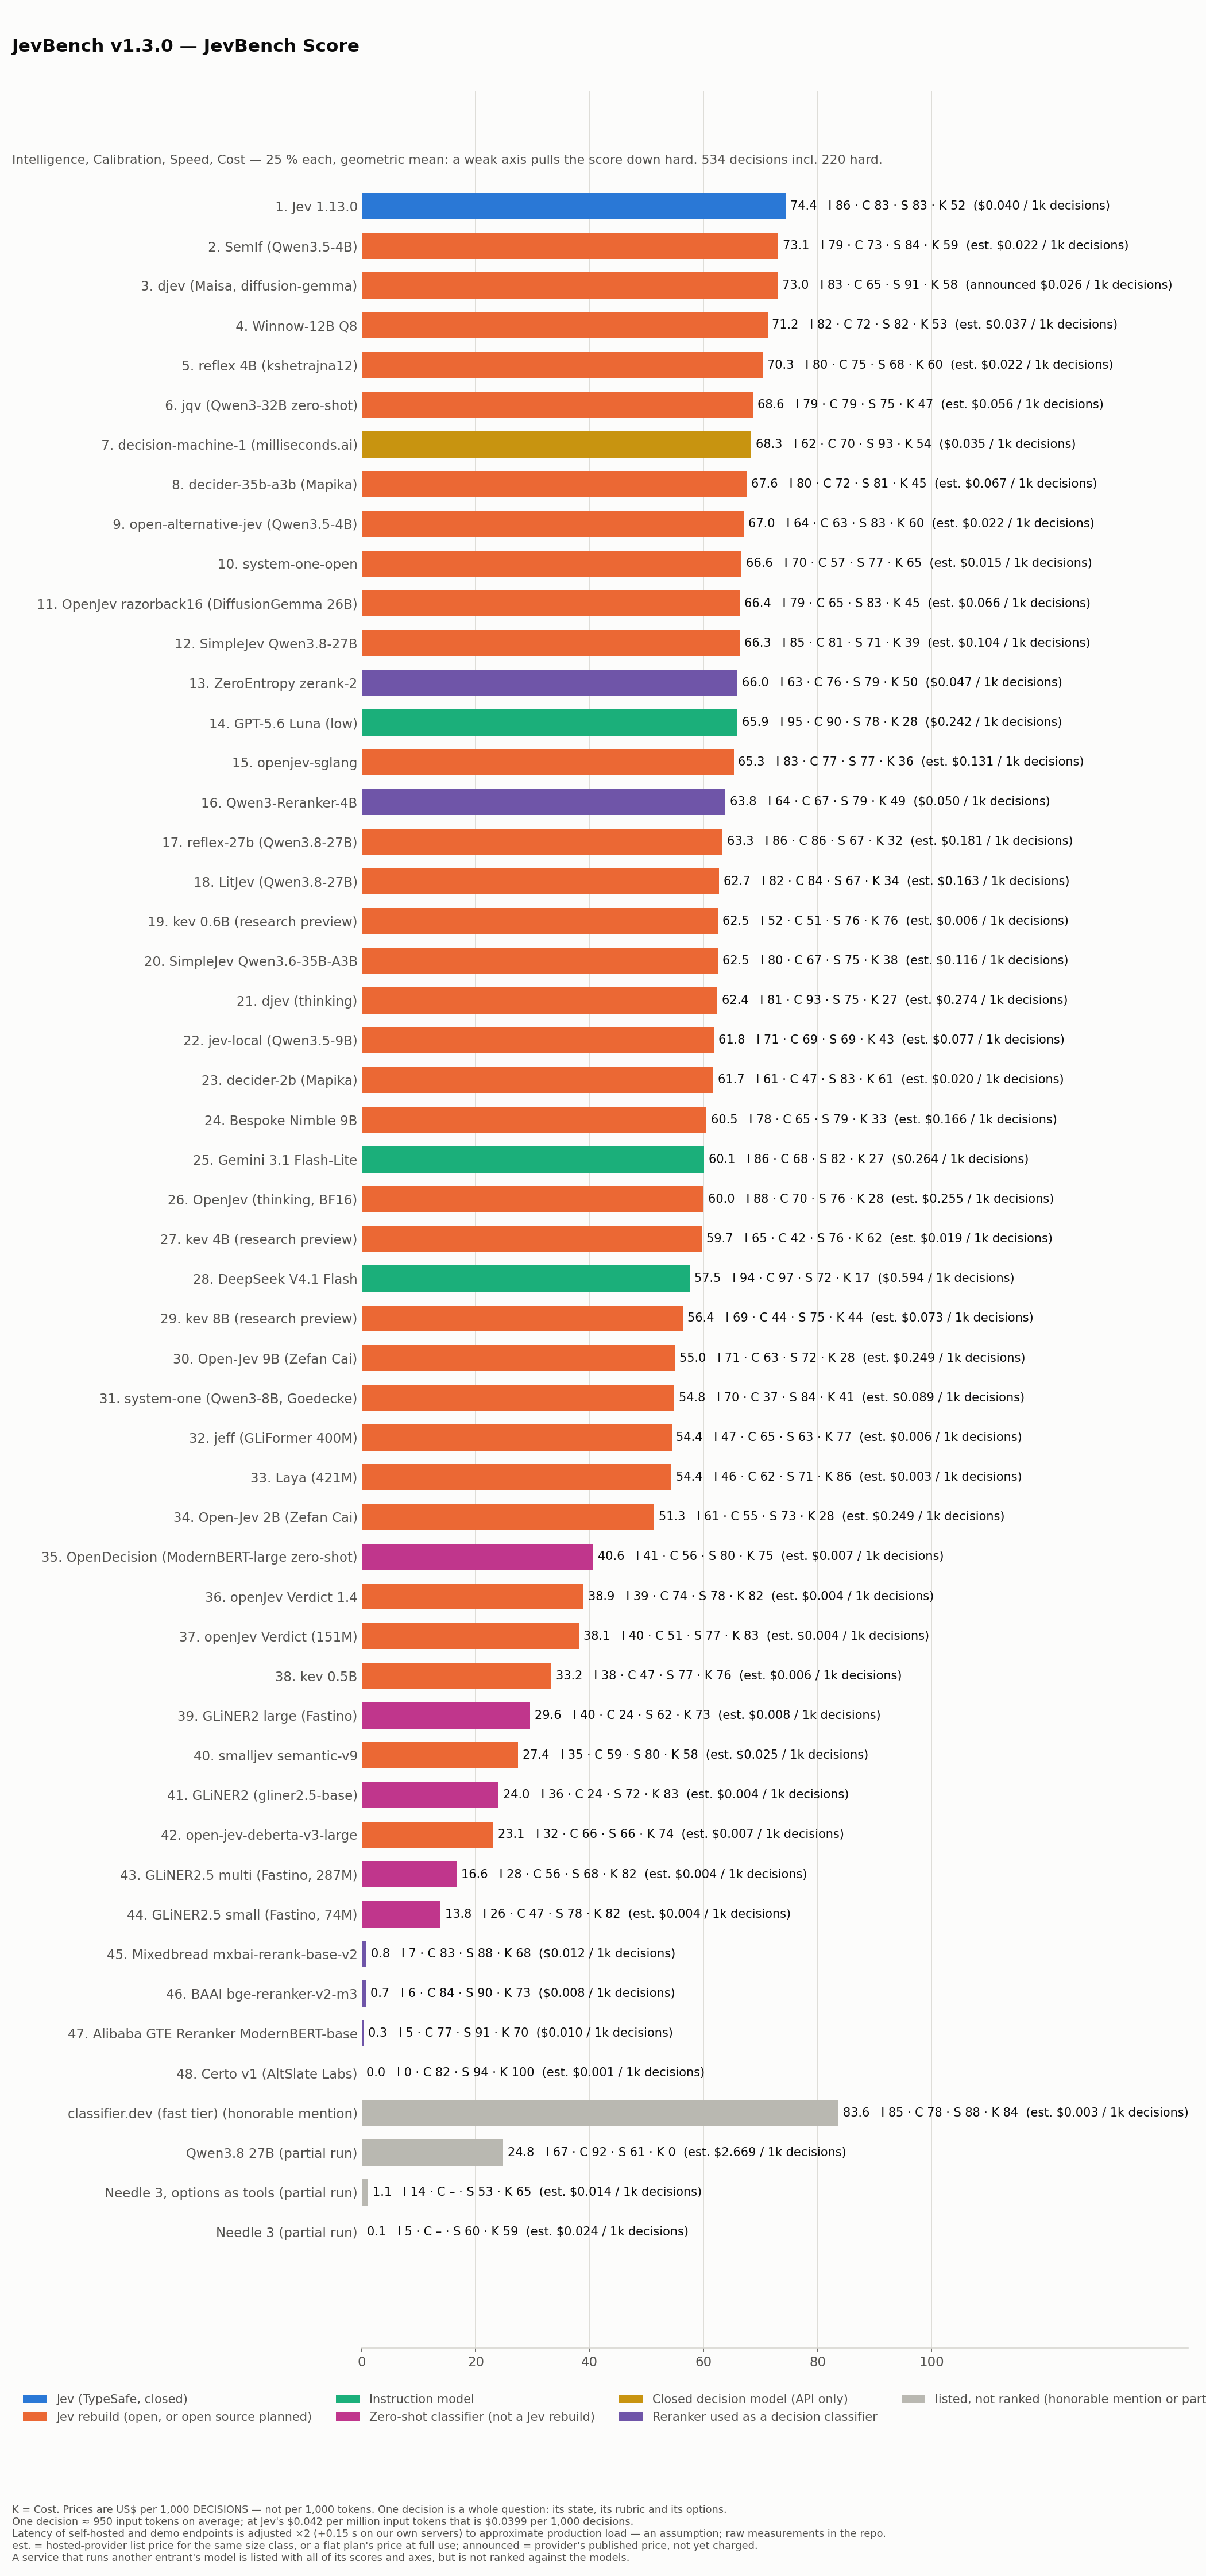
JevBench Score = chance-corrected Intelligence, Calibration, Speed, Cost — 25 % each, geometric mean. Below 50 Intelligence, multiply the score by (Intelligence / 50)².
| Axis | Score 0-100 |
|---|---|
| Intelligence | (accuracy - chance) / (1 - chance) per tier, clipped at 0; hard 30 %, easy 14 %, standard 28 %, judge 28 % |
| Calibration | hard tier: ECE + fidelity to exact gold distributions (label-only systems: none, counts as 0) |
| Speed | mean of score(p50), score(p95); score(s) = 100 - 20 log10(s / 0.1 s): 0.1 s = 100, each 10x slower -20 |
| Cost | 100 - 30 log10($ per 1,000 decisions / $0.001): $0.001 = 100, each 10x more expensive -30 |
The Cost column is US dollars per 1,000 DECISIONS, not per 1,000 tokens. One decision is a whole question: its state, its rubric and its options — hundreds to thousands of input tokens. Jev 1.13.0 reads 950 input tokens per decision on average over the 534 v1.2 decisions. At its public tariff of $0.042 per MILLION input tokens (output tokens are free, https://docs.typesafe.ai/models), 1,000 decisions therefore cost 950 x 1,000 x $0.042 / 1,000,000 = $0.0399. That is what the Cost column shows: $0.0399 per 1,000 decisions, not per 1,000 tokens.
Latency of self-hosted and demo endpoints is adjusted ×2 (+0.15 s on our own servers) to approximate production load — an assumption, not a measurement; raw measurements are in
RESULTS-v1.2.mdand the artifact. Why, and its limits: Limits, stated plainly.
-
Accuracy by subject topic (math, coding, rules & law, finance, support & operations, everyday language, safety & security):
datasets/TOPICS.mdandresults/v1.2/jevbench-v1.2-topics.json— aggregates only, not part of the score. -
220 hard decisions (111 public in
datasets/public/hard.jsonl, 109 held out), written by Claude Opus 5 and GPT-5.6 Sol, cross-reviewed, frozen and hashed before any system ran; 534 decisions per system in total. -
Top of the ranking (48 ranked rows): Jev 1.13.0 (TypeSafe AI) 74.4 · SemIf, formerly OpenJev (Qwen3.5-4B, TheoLeeCJ) 73.1 · djev (Maisa, diffusion-gemma) 73.0 · Winnow-12B Q8 71.2 · reflex 4B (kshetrajna12) 70.3. Qwen3.8 27B and Needle 3 (both modes) are partial runs, shown without a rank.
-
djev is self-hostable:
Davipar/djev-devis Apache-2.0 code over Google's Apache-2.0 DiffusionGemma weights. It is an inference method, not a separately trained model, and adds no weights of its own.djev-sparkis another DiffusionGemma structured-read runtime, not another model row. -
Honorable mention, not ranked: classifier.dev (fast tier) 83.6. A service that runs another entrant's model is listed with all of its scores and axes, but is not ranked against the models — its fast tier is Jev ("The fast tier is Jev, TypeSafe's decision model", classifier.dev/benchmark), so ranking it would rank Jev's model against Jev's model at a different price. See Honorable mentions.
-
Scoring code:
jevbench/composite_v13.py; the final artifact is rebuilt from the frozen measurements byscripts/v1.2/finalize.py, charts byscripts/v1.2/charts.py. Per-task outcomes (public items):results/v1.2/jevbench-v1.2-per-task.json. -
open-alternative-jev is ranked with the author's own option order (
A. yes, B. no). With the options in reverse order (A. no, B. yes) the same model scored 21 % instead of 72 % on answer-judging items — small models are very sensitive to option order. Both runs:results/v1.2/runs/open-alternative-jev/.
Other mentions and diagnostics
- stuntdouble is an independent shadow-proxy and replay companion that can import JevBench's public hard items to compare local decision models. It is a tool, not a JevBench entrant; its example report is not an official JevBench result.
- The option-order robustness analysis in issue #40 is a separate diagnostic on public choice items. It does not change the canonical task order or official scores.
What changed in the score
A system that is cheap and fast but barely better than guessing could rank high; intelligence is now measured above chance, and systems below half-way get a growing penalty. The task set, Calibration, Speed, Cost and who is eligible for a rank are unchanged.
Revision log of v1.2 (19 Sep 2026; items and answers never changed after the freeze):
v1.2-wip (tag v1.2-wip) hard tier + calibration sub-score, Balanced 33:33:33 Main Score with hard 50 % of Capability;
v1.2 final (tag v1.2): 4 axes, geometric mean — Intelligence (hard 30 %), Calibration, Speed, Cost at 25 % each; Speed 20 points
and Cost 30 points per decade; latency of non-production endpoints adjusted ×2 (+0.15 s on our own servers, an assumption);
one open-alternative-jev row (author's option order); Needle 3 options-as-tools priced on Needle 3's per-token basis ($0.0162 est.).
The earlier weightings are kept as views, recomputed the same way, and are not the JevBench Score.
v1.2.1 (tag v1.2.1): added djev (Maisa's diffusion-gemma Jev-compatible implementation, api.djev.dev) — all 534 decisions including the
held-out items, one request at a time through its production API (no latency adjustment), scored with the unchanged v1.2 rules.
Cost uses djev's announced price ($0.035 per million input tokens, output free), which is not charged yet (free preview).
Adapter: jevbench/adapters/djev.py; row: results/v1.2/additions/djev.json.
No other row changed; ranks below #2 move down one.
v1.2.2 (tag v1.2.2): five systems readers asked for — Laya (Convai Innovations,
ModernBERT-large 421M), jeff (Logan Markewich, GLiFormer 400M),
GLiNER2 (Fastino, gliner2.5-base), openJev Verdict
(heman10x, 151M) and classifier.dev (fast tier). Each ran all 534 decisions including the held-out ones, with the
unchanged v1.2 scoring. The four open systems ran on our CPU (4 threads) and carry the usual ×2 + 0.15 s latency adjustment; classifier.dev is a
production API and carries none. Every mapping — above all GLiNER2's label scores → one distribution — was written down before the runs:
docs/v1.2-additions.md. Adapters: jevbench/adapters/ (laya_local, gliner2_local,
verdict_local, classifier_dev; jeff uses the existing typesafe adapter against its own server). Rows:
results/v1.2/additions/. No other row changed.
ProgramAsWeights was also requested and is prepared (paw_local), but its hosted compiler only keeps a program private for a signed-in
account, and compiling 223 held-out rubrics into public programs would publish them; it is therefore not in this revision.
v1.2.3 (tag v1.2.3): cost correction. Every row's price was recomputed so that each of the 534 decisions is counted once and
priced once. Three arithmetic mistakes were fixed — the 242-decision standard+judge run was averaged twice in the v1.1-tier price
(556 rows instead of 314); rows priced from the gemini-3.1-flash-lite token counts used that run's standard+judge-only average
(452 input tokens per decision) for all 314 v1.1 decisions instead of its average over all 314 (383); and requests whose answer came
back unparseable were left unpriced although the provider billed them (9 DeepSeek V4.1 Flash decisions).
No tariff was wrong, no measurement, item or answer changed, and no rank changed. Fifteen rows become 1.5–11 % cheaper
(JevBench Score up by at most 0.2 points); DeepSeek V4.1 Flash becomes 2.6 % more expensive. The correction also spells the unit out
everywhere: the Cost column is dollars per 1,000 decisions, never per 1,000 tokens. Per-row figures and their derivation:
results/v1.2/cost-correction-v1.2.3.json; check:
tests/test_cost_correction.py.
v1.2.4 (tag v1.2.4): classifier.dev leaves the ranking and becomes an honorable mention. New general rule: a
service that runs another entrant's model is listed, but not ranked against the models. classifier.dev is not its own
model — its own pages say "The fast tier is Jev, TypeSafe's decision model"
(classifier.dev/benchmark, read 20 Sep 2026) and the API answers with
"model": "jev-1.13.0" — so ranking it put the same model in the list twice, once at TypeSafe's per-token tariff and
once at classifier.dev's flat plan. What it adds is that price and, on its smart tier (which we did not measure),
an orchestration layer: "The smart tier is Jev plus a reasoning model re-asking only the answers Jev put under 0.7
confidence" — escalation on low confidence, a model cascade, not best-of-N, self-consistency or a committee.
Its row keeps every number, axis, cost basis, radar and per-task outcome and carries no rank; Jev 1.13.0 is #1 and
every other row moves up one place. No measurement and no score changed. The full note, with the price caveat and the
one place where the fast tier measurably differs from Jev, is in
RESULTS-v1.2.md; check:
tests/test_honorable_mentions.py.
v1.2.5 (tag v1.2.5): the kev family. Added kev 0.5B and its 0.6B, 4B and 8B research previews. Each ran all 534 frozen decisions through the author's native TypeSafe-compatible endpoint in BF16 on one RTX 3090, with zero failed requests. kev 0.6B enters highest at #9 with 66.7; 0.5B is #15 with 63.1, 4B #16 with 62.2, and 8B #18 with 58.3. The larger checkpoints improve Intelligence but lose points on calibration and estimated hosted cost. No earlier row changed.