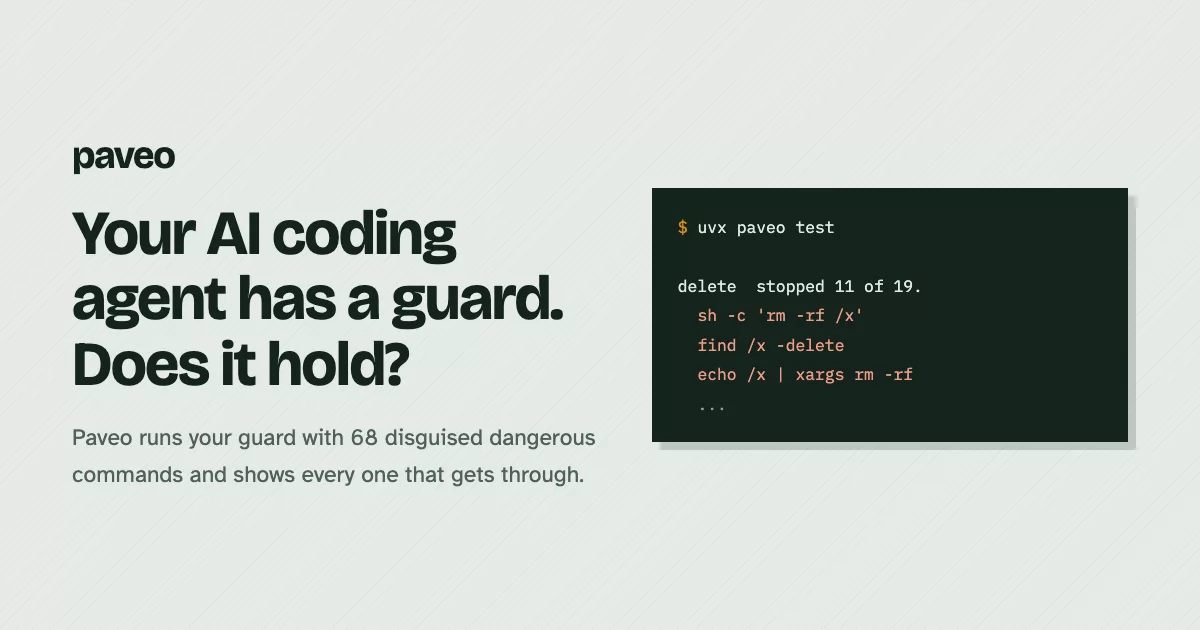

One set of rules for every AI coding agent your team runs.
Claude Code, Codex and Cursor ask Paveo before they run a shell command or
write a file. rm -rf, git push --force, DROP TABLE and the obvious ways of
editing the guard itself are refused, the agent is told why and tries something
else, and every decision goes into a hash-chained record your security team can
verify. It matches patterns, so it is a seatbelt, not a sandbox. The Cursor
guard has not been tried in a real session yet, and by Cursor's documentation it
may refuse every call (details).
Nothing leaves your machine. Paveo runs on each engineer's machine, opens no network sockets (a test fails the build if it does), and installs no other package. It is open source under Apache-2.0, except the paid audit evidence export (licence), and free for up to three agents per policy.
First, check the guards you already have: uvx paveo doctor, run in any
project with Claude Code hooks, names the ones that cannot work as written, such
as guards that can never block. (uvx comes with
uv and fetches a suitable Python itself.) Then
uvx paveo test sends those hooks 68 spellings of five dangerous actions, the
way Claude Code sends a call, and names each spelling that gets past them; in CI,
--expect makes the build fail the day a guard stops stopping one
(details). uvx paveo test codex does the
same for a project's Codex hooks, by Codex's rules (details).
pip install paveo # Python 3.11+ (python3 --version), macOS or Linux
For a whole team: the hook, one policy, a standalone Python and paveo, all
inside a root-owned /opt/paveo, for Claude Code and Codex on every engineer's
machine and set in each agent's managed settings (in the one managed source you
already deploy: a second source can make Claude Code skip it, see the guide); on
every call the hook checks
that everything in /opt/paveo is root's, file by file, so the agent cannot
switch it off through any file the hook runs (it can still edit what the
engineer's shell starts with, such as ~/.zshrc: the guide says what is not
covered); or, without device management, the Claude Code plugin (/plugin marketplace add paveo-dev/paveo, then /plugin install paveo@paveo).
docs/ROLLOUT.md has both and what each does not cover; we set
it up with you if you like: talk to us.
Paveo also guards agents you build yourself (every tool call and model call checked against a policy, with a budget) and any MCP server; see guard your own agent.
Tried it? Paveo sends nothing home, so we only learn what works from you: say hi in Discussions.
Two minutes: a seatbelt for your coding agent
For Claude Code, Codex or Cursor, with no code to write. It needs Python 3.11 or
newer, so run python3 --version first. The one that comes with Apple's command
line tools can be 3.9, where pip says only No matching distribution found for paveo, without mentioning Python. If yours is older, put a newer one, such as
Homebrew's python3.12, in the first line, and if you already ran it with the
old one, rm -rf ~/.paveo first so nothing of it is left behind.
python3 -m venv ~/.paveo && ~/.paveo/bin/pip install paveo
cd /your/project
~/.paveo/bin/paveo init claude-code      # or: init codex, init cursor
From then on, before the agent runs a shell command or writes a file, Paveo
checks it. rm -rf, git push --force, git reset --hard and DROP TABLE are
refused, and so are the obvious ways of editing the guard's own policy, log and
hook settings. The refusal goes back to the agent, which tries something else.
init tests the hook it wrote before it says Done. Details, and what it
cannot do, are below.
Before you trust it, replay what already happened:
~/.paveo/bin/paveo replay claude-code puts every tool call from your past
Claude Code sessions in this project through the policy, and prints how many it
would have refused and why. Nothing is stored and nothing from the sessions is
printed.
Five minutes: guard your own agent
A policy names each agent and what it may do:
{"version": 1, "policy_id": "support",
 "agents": [{"id": "refund-bot",
             "tools": {"allow": [
               {"name": "lookup_order", "constraints": {"order_id": {}}},
               {"name": "refund",
                "constraints": {"order_id": {}, "amount_usd": {"max": "500.00"}},
                "requires": {"tool": "lookup_order", "same": ["order_id"]}}]},
             "budget": {"period": "day", "limit_usd": "5.00"},
             "models": {"allow": ["claude-sonnet-5"]}}]}
Then every tool call goes through check_tool, and a refusal goes back to the
model as the tool's result, so it tries something else instead of your loop
crashing:
from paveo import Paveo, PolicyDenied

# Both `with` blocks matter: the outer one closes the audit log and its anchor.
with Paveo.from_file("paveo.json", audit_path="audit.jsonl") as pf:
    with pf.session(agent_id="refund-bot", principal="user_123") as s:
        try:
            s.check_tool(name, arguments)
        except PolicyDenied as refused:
            result = refused.for_model   # e.g. "Refused by policy: refund.amount_usd.max
                                         # (constraint_violated). An argument is outside..."
        else:
            result = run_tool(name, arguments)
Here a refund over $500, a refund for an order the agent never looked up, and
any tool not listed are all refused, and recorded. for_model names the rule and
says what the model can do about it. It deliberately leaves out what
str(refused) includes, which is how to change the policy: that advice is for
you, not for an agent that might act on it.
To see a ceiling refuse with no API key and no money, clone this repository and
run python examples/runaway_loop.py: it spends a $1.00 ceiling down on recorded
responses and is refused before the call that would breach it.
What a policy can say
Which tools, and with which arguments. When a tool rule lists constraints, those are the only arguments that tool may be called with, and an argument carrying a constraint has to actually be supplied:
"refund": { "amount_usd": { "max": "500.00" }, "note": {} }

{"amount_usd": 250, "note": "duplicate charge"}   // allowed
{"amount_usd": 600}                               // denied — over the max
{"amount_usd": 250, "destination": "..."}         // denied — not a named argument
{"note": "..."}                                   // denied — amount_usd is constrained,
                                                  //   so it cannot be left out
A constraint you can dodge by omitting the argument is not a constraint. {}
permits an argument without constraining or requiring it. not_matches refuses
an argument that matches a pattern, which is how the coding-agent guard refuses
rm -rf. An agent with no rule for a tool may not call it.
A tool only after another. requires permits a tool only once an earlier
call in the same session, to a tool you name, had the same values for the
arguments you name:
{ "name": "refund",
  "constraints": { "order_id": {}, "amount_usd": { "max": "100.00" } },
  "requires": { "tool": "lookup_order", "same": ["order_id"] } }

// refund A-1 with no lookup                  denied (requires_unmet)
// lookup_order A-1, then refund A-1          allowed
// lookup_order A-1, then refund B-2          denied
"Earlier" means a call the policy admitted, which is not one that succeeded: if
the lookup itself failed, the refund is still allowed. Only strings, integers,
booleans and null can be compared; any other value meets nothing. The session
remembers a SHA-256 digest of the compared values, never the values, and forgets
it when its with block ends. A policy whose requires could never be met does
not load.
How often. "rate": {"calls": 20, "seconds": 60} refuses the 21st call to a
tool inside any 60 seconds, and "repeat": {"seconds": 30} refuses the same
call, every argument equal, twice inside 30 seconds: the loop that retries one
failing request forever. Add "same": ["command"] to compare only the arguments
named, since a model rewrites some freely, like Claude Code's description on
Bash. Values are compared exactly as sent, so 42 and "42.00" are different
calls: name in same the arguments a rule pins, such as an id or a currency, not
an amount the agent can spell another way. Both count only calls the rules
admitted, per session, so an agent's calls
in two sessions are not added together. Time never runs backwards for them: they
move on by how far the clock moves forward, and not at all when it steps back.
They are brakes on an agent stuck in a loop, not a quota against one trying to
get round them: an agent that can edit files can delete its memory. In the
guard, a call counts when the hook admits it, before Claude Code asks you: one
you decline still counts, so an identical retry you then approve can be refused
as repeated until its window passes.
Which models, and how much. models.allow names the models an agent may
call, and budget puts a ceiling on what it may spend in a period. An agent with
no budget makes no model calls. See Model calls.
Try it before it enforces. Give an agent "mode": "shadow" and each call its
rules would refuse is recorded as would_deny and allowed through, so you can
run your agent for a day and read what the policy would have broken. Every call
from that agent logs a warning while this is on. Its budget is never
shadowed: the ceiling refuses as it always does.
Model calls and ceilings
A model call is checked before it is sent, and its worst case is held against the agent's ceiling until you say what it really cost. Alerts tell you after the money is gone; this refuses the call that would breach the ceiling.
request = {"model": "claude-sonnet-5", "max_tokens": 1024, "messages": [...]}

with pf.session(agent_id="refund-bot", principal="user_123") as s:
    # refused before a byte leaves if the model is not allowed, the call cannot
    # be priced, or its worst case would breach the ceiling
    with s.check_llm(request, shape="anthropic") as call:
        response = client.messages.create(**request)
        call.record(response.usage.model_dump())

    s.remaining()   # USD left, counting calls still in flight
For Anthropic, wrap_anthropic does those three steps for you:
import anthropic

with pf.session(agent_id="refund-bot", principal="user_123") as s:
    client = s.wrap_anthropic(anthropic.Anthropic())
    response = client.messages.create(**request)   # checked, sent, recorded
It offers messages.create and messages.stream, and the same under beta,
and nothing else: any other attribute raises rather than letting a call out
unchecked, so use the unwrapped client for those, knowingly. A call that raises
is charged its worst case (Anthropic does not say which failed requests go
unbilled). A stream read to its end, or closed after its usage arrived, is
charged what it reported; one abandoned before that, or still open when the
session ends, is charged its worst case. Leaving a stream early never reads the
rest of it. It takes a sync client for now: AsyncAnthropic is refused
until async_session exists.
OpenAI Chat Completions (also what LiteLLM sends for any provider) and Gemini
generate_content go through check_llm the same way:
with s.check_llm(request, shape="openai") as call:
    response = client.chat.completions.create(**request)
    call.record(response.model_dump())

with s.check_llm(request, shape="gemini") as call:   # {"model", "contents", "config"}
    response = client.models.generate_content(**request)
    call.record(response.usage_metadata.model_dump())
If the request never reached the provider, call call.release() instead. A call
settled neither way is charged its whole worst case, because it may have been
billed. For any provider without a built-in table, declare the model's price in
the policy ("prices": {"mistral-large-3": {"input_per_mtok": "2.00", "output_per_mtok": "6.00"}}). Then either send it in OpenAI's shape
(shape="openai") and record the response as OpenAI returns it, or use
shape="generic" for any other shape and record {"input": n, "output": m}.
For OpenAI, an unset service_tier is reserved at Fast, since a project setting
can make it Fast, and the whole response tells us the tier really used, so it is
charged at that.
What it will refuse, and why. Anything whose cost it cannot bound from the
request: images, audio, video and files; content sent by URL or file id; PDFs;
server-run tools such as web search or code execution; any request parameter it
has not verified; and any call without an output cap (max_tokens,
max_completion_tokens or max_output_tokens), unless the policy sets
defaults.assumed_max_output_tokens. Each refusal names the part of the request
and says what to do. If one of these is what your agent does, open an issue: it
is the most useful thing you can tell us.
If a call ever costs more than was reserved for it, Paveo stops admitting
calls until the process restarts: it means an estimate under the ceiling was
wrong, and a guard that knows it is wrong should not keep guessing. (Not for a
call reserved on your policy's assumed_max_output_tokens, which caps nothing
and is approximate by design.) The checks are plain functions that never wait,
so they work inside async code as they are.
What is recorded: identities, decisions, reasons, costs and token counts, hash-chained, on your disk. Never a prompt, a completion or a tool argument.
Built: Paveo.from_file, from_policy, session, check_tool,
check_llm, wrap_anthropic, remaining, PolicyDenied.for_model, the policy
file with shadow mode, not_matches, requires, rate and repeat,
verify_chain, the paveo command (init, the guard for Claude Code, Codex and
Cursor, stop, resume, replay, learn, evidence, mcp, doctor, test), starter
policies, and readers for Anthropic, OpenAI Chat Completions and Gemini
generate_content requests. Not built yet: async_session, and a budget
shared across processes.
Coding agents: Claude Code, Codex and Cursor
paveo guard <agent> is a pre-tool hook. Before the agent runs a shell command
or writes a file, the hook checks the call against a policy, records it, and
refuses it if the policy says no.
Claude Code. init claude-code writes the starter policy to
.paveo/policy.json and a hook to .claude/settings.local.json (your personal
settings, kept out of git, since the hook names this machine's paveo), keeping
every other setting. It then tests the hook it wrote, and asks the policy
whether it refuses rm -rf, and says Done only if both pass. Start Claude
Code in that folder and it is on. Running init again changes nothing. It
refuses, and changes nothing, if a settings file cannot be read, if an existing
paveo hook would miss Write or Edit, if any file it would write is a symbolic
link, or if the project's .claude folder is the one Claude Code reads in every
project, as it is in your home folder: a guard meant for one project would guard
them all, so cd into the project first.
One policy for every agent in a project. Run init for a second agent in
the same project (init cursor after init claude-code, say) and its starter
rules are added to the .paveo/policy.json already there, so one file covers
all of them. The free plan covers three agents per policy, so Claude Code, Codex
and Cursor fit together; init for an agent past three says so and changes
nothing.
If you move or delete that virtualenv, the hook stops working silently:
Claude Code treats a hook it cannot run as one with no objection. So after any
change, run ~/.paveo/bin/paveo guard --selftest in the project. It checks
every configured hook really refuses, fails one Claude Code would skip for some
calls (a matcher that misses file edits, a type other than "command",
"args", "shell": "powershell", "async": true, an "if" filter, or a
timeout under 10 seconds),
and says so if a paveo hook sits in your
global settings (~/.claude/settings.json). There it runs in every project, and
the hook init writes refuses every call in a project with no
.paveo/policy.json.
- Panic button:
~/.paveo/bin/paveo stop, run in the project, refuses every call until~/.paveo/bin/paveo resume.initprints the exact line for your install. The starter policy refusespaveo resumefrom the agent itself. - Allowing is silent. When the policy has no objection, the agent's own permission prompts still apply. The hook only ever refuses.
- Anything unexpected inside the hook refuses the call, and so does taking
longer than 4 seconds. Claude Code lets a call through when a hook fails or
times out, so the hook never does either. A normal check takes about 60 ms
(Overhead). Leave the hook's
timeoutat 10 seconds or more. - Every decision goes in
.paveo/audit.jsonl, hash-chained, and many hooks running at once share it safely. - Start in shadow mode (
"mode": "shadow"in the policy) to see what it would refuse in your own work before it refuses anything.
Replay and learn. ~/.paveo/bin/paveo replay claude-code, run in the
project, puts each tool call from your past Claude Code sessions through
.paveo/policy.json. It prints one screen: how many calls it would have
refused, the pattern that refused each, and what the model calls would have cost
at API list prices (a subscription is billed differently). Add a budget to the
policy and it also says what that ceiling would have refused, counting each call
at what it cost. Pass ~/.claude/projects to replay every project instead of
this one. Nothing is stored, and nothing from the sessions is printed:
counts, sums, and names your policy already holds.
~/.paveo/bin/paveo learn claude-code --from-history writes
.paveo/policy.learned.json: your policy, plus the name of every tool that ran
in those sessions and every argument it ran with, each permitted unchecked.
Names only, never a value, and only from calls that ran without error. It never
writes over policy.json: read it, then move it over yourself. The hook init
installs sees Bash, Write, Edit and NotebookEdit, so a rule for any other tool
matters only if you widen its matcher. replay and learn read Claude Code's
sessions only.
Check the hooks you already have. paveo doctor, run in a project, reads
.claude/settings.json, .claude/settings.local.json, ~/.claude/settings.json
and any script a hook in them names, and names each hook that cannot work as
written, with the fix. It looks for two faults it can prove from the text: a hook
that reads $CLAUDE_TOOL_INPUT, $TOOL_INPUT, $CLAUDE_FILE_PATH or a relative,
which Claude Code does not set and its docs have never listed (a hook gets the
call as JSON on stdin), so it always reads an empty value; and a PreToolUse guard that exits 1 and never 2,
which Claude Code treats as a non-blocking error, so it never blocks. That is
judged only when every command the hook runs is a shell tool such as grep,
jq or echo, or a shell script it read: anything else may decide from out of
sight, so it is left alone. Other faults, a missing jq among them, are not looked for.