Rapid-MLX
Run Codex, Claude Code, OpenCode, Pi, Hermes, Crush or Goose with a local model on Mac:rapid-mlx launch <agent>
Install on a stock Apple Silicon Mac with curl -fsSL https://rapidmlx.com/install.sh | bash, restart your terminal (or run export PATH="$HOME/.local/bin:$PATH"), then install your chosen coding agent and run, for example, rapid-mlx launch codex. Run the same command tomorrow; rapid-mlx launch codex --remove removes Rapid's private profile without changing your existing Codex settings. One-command guides for each agent. A first reply can take longer while a model downloads, loads, or processes the agent's opening prompt.
Rapid-MLX is an open-source (Apache 2.0) OpenAI- and Anthropic-compatible LLM inference server for Apple Silicon, built on MLX, focused on reliable tool calling for coding agents.
Up to 4× faster than Apple's MLX (mlx-lm), 1.5× on a typical task — same model, same weights.
Decode speed, Qwen3.5-9B 4-bit on a Mac mini M4 Pro, greedy decoding, both servers at their defaults — per-task results, method, and raw data.
Faster decode than oMLX and LM Studio on Qwen3.5-9B, Qwen3.8-27B, and Qwen3.6-35B
Measured speed on a Mac Studio M5 Max (36 GB) — Rapid-MLX 0.16.1 vs oMLX 0.7.0 and LM Studio, using the same base 4-bit weights for each model.
| Model | Metric | Rapid-MLX | oMLX | LM Studio |
|---|---|---|---|---|
| Qwen3.5-9B | Decode (tok/s) | 115.5 | 77.9 | 81.0 |
| Qwen3.5-9B | 4 streams (tok/s) | 248.2 | 224.6 | 230.0 |
| Qwen3.8-27B | Decode (tok/s) | 37.9 | 25.3 | 26.0 |
| Qwen3.8-27B | 4 streams (tok/s) | 82.8 | 75.3 | 69.7 |
| Qwen3.6-35B | Decode (tok/s) | 173.4 | 145.8 | 124.5 |
| Qwen3.6-35B | 4 streams (tok/s) | 293.9 | 281.9 | 265.6 |
| Qwen3.6-35B | 2K-prompt first token (s, lower is better) | 0.55 | 1.14 | 1.49 |
Single run per engine; default serving modes with Rapid's MTP text mode, oMLX's SSD cache, and LM Studio's configured context and four parallel slots. Full results and raw data.







rapidmlx.com · Docs · Model mirror · Desktop app · Discord
How it compares
Feature facts only, taken mostly from each project's own documentation as of 2026-09-26 (sources below). For speed, see the measured results above.
| Rapid-MLX | oMLX | Ollama | LM Studio | mlx-lm (mlx_lm.server) |
|
|---|---|---|---|---|---|
| License | Apache-2.0 | Apache-2.0 | MIT | Closed-source app; its MLX engine and lms CLI are MIT |
MIT |
| Inference engine on a Mac | MLX | MLX | GGML/GGUF engine, plus an MLX engine for safetensors models | llama.cpp (GGUF) and MLX engines | MLX |
| Local API | OpenAI (/v1/chat/completions, /v1/responses) and Anthropic Messages (/v1/messages) |
OpenAI and Anthropic Messages | Ollama API, OpenAI-compatible, Anthropic-compatible (subset) | OpenAI-compatible, Anthropic-compatible, LM Studio REST API | OpenAI-style chat API |
| GUI | Rapid-MLX Desktop (macOS app) | macOS menu-bar app and web admin panel | Desktop app (macOS, Windows) | Desktop app | None (CLI / Python) |
| Concurrent requests | Continuous batching | Continuous batching (mlx-lm BatchGenerator) |
Parallel requests per model (OLLAMA_NUM_PARALLEL, default 1) |
Continuous batching (llama.cpp engine; MLX engine since 0.4.2) | Continuous batching (BatchGenerator); one request at a time with a quantized KV cache |
| Prompt / KV cache | Radix prefix cache in memory (with state snapshots for hybrid models), saved to disk on shutdown and restored at startup; quantized KV cache | Tiered KV cache: in-memory hot tier plus SSD cold tier, reused across restarts | Reuses the previous request's prompt KV cache; KV cache quantization (OLLAMA_KV_CACHE_TYPE) |
— | In-memory prompt cache; quantized KV cache (--kv-bits) |
| Tool-call parsing | 27 parser modules, including an auto-detect fallback (rapid_mlx/tool_parsers) |
mlx-lm formats plus the auto-detected families listed in its README | Tool calling | Tool use via the OpenAI-compatible API | Tool calls for models whose tokenizer declares tool-calling support |
Sources: oMLX README ·
Ollama OpenAI and Anthropic compatibility, FAQ, MLX engine ·
LM Studio Anthropic compatibility, parallel requests, 0.4.2 changelog, app terms, mlx-engine ·
mlx-lm server docs and server.py.
Ollama prompt-cache reuse is from our benchmark notes.
— = not verified for this table. Spot an error? Please open an issue.
vs Apple's mlx-lm: per-task results and raw data at https://rapidmlx.com/compare/mlx-lm.
Works with your AI stack
Use Rapid-MLX as a local backend for agents, apps, or your own code. If a client accepts an OpenAI- or Anthropic-compatible endpoint, it can usually use Rapid-MLX without an adapter.
For Claude Desktop, set up its in-app Gateway.






Five Tier-1 agents are exercised end-to-end on real weights before release. See the tested compatibility matrix for exact API coverage and setup status.
Install
Desktop — macOS (Apple Silicon)
The easiest way to chat locally, manage models, and use vision, files, voice, and image generation from one app.
- Download Rapid-MLX Desktop
- Browse signed Desktop releases
- Requires an M-series Mac; Windows and Linux desktop builds are not available yet
- Share Compute setup and credit ledger
CLI and server — macOS (Apple Silicon)
# Homebrew — prebuilt bottle from homebrew-core
brew install rapid-mlx

# Or the guided installer — detects RAM and recommends a starter model
curl -fsSL https://rapidmlx.com/install.sh | bash
Both install the same rapid-mlx CLI. Prefer uv or pip, or want to verify
the installer before running it? See alternative install methods
and install security.
The guided installer prefers a runnable model already cached on this Mac when
it fits the RAM tier. Otherwise its quick first-chat download is
lfm2.5-1b-4bit below 16 GB and qwen3.5-4b-4bit at 16 GB or above; larger
quality picks remain available through rapid-mlx recipe and the model picker.
Submit a Community Benchmark
Help other Mac users choose a model by sharing a standardized result from your own Apple Silicon Mac. Runs stay local until you explicitly choose to publish; you do not need a GitHub account or a benchmark JSON pull request.
- Desktop: Enable Community Benchmark in Settings → Experimental, then choose a model in the Community Benchmark tab, run it, review the result in My Results, and select Publish if you want to share it.
- CLI: Run
rapid-mlx benchmark catalog, thenrapid-mlx benchmark run <model>. Review the saved result and publish it withrapid-mlx benchmark share <run-id>only if you choose to.
Explore the Community Benchmark leaderboard or read the protocol and privacy details.
Quick Start (60 seconds)
1. Chat with a model right now:
rapid-mlx chat
A complete cached chat model that fits this Mac starts without another download. Otherwise Rapid-MLX selects a starter model and downloads its weights before opening the REPL. Type /help for slash commands, /exit to quit.
2. Or serve it for use from other apps:
rapid-mlx serve qwen3.5-4b-4bit
Starts an OpenAI-compatible HTTP server on the first free port in 8000–8009 when --port is omitted. An explicit --port never falls back. The examples below assume port 8000 was selected. Point any client that supports a local custom endpoint (Aider, LangChain, OpenCode, PydanticAI, your own scripts) at http://localhost:8000/v1; Claude Code / Anthropic SDK uses http://localhost:8000 (the Anthropic messages route lives at /v1/messages under the same host).
curl http://localhost:8000/v1/chat/completions \
  -H "Content-Type: application/json" \
  -d '{"model":"default","messages":[{"role":"user","content":"Say hello"}]}'
from openai import OpenAI
client = OpenAI(base_url="http://localhost:8000/v1", api_key="not-needed")
print(client.chat.completions.create(
    model="default",
    messages=[{"role": "user", "content": "Say hello"}],
).choices[0].message.content)
3. Or wire up your coding agent — one command:
rapid-mlx launch claude-code
This saves a private Claude Code profile, starts a local server if needed, and launches Claude Code without editing ~/.claude/settings.json. The same command works after a restart. Swap in codex, opencode, pi, hermes, crush, or goose. For the original config-writing behavior, use --legacy-config; cline and continue-dev keep their existing setup flow.
Cursor: Cursor currently routes BYOK requests through its own servers, so its servers cannot reach a Rapid-MLX endpoint on
localhost. Rapid-MLX therefore does not generate a Cursor localhost config. If you intentionally expose the server through a public HTTPS tunnel, setRAPID_MLX_API_KEY=your-secretfor bothrapid-mlx serve ...andrapid-mlx launch cursor --server-url https://your-public-host. This is no longer a fully local connection; never expose an unauthenticated server. Rapid-MLX rejects explicit local/private addresses but cannot verify reachability from Cursor's network, whose DNS view may differ from your Mac.
Vision / image / video models? They work out of the box with the official installer above (and Rapid-MLX Desktop), which include the vision, image-generation and video-generation runtimes (image and video generation need Python 3.11+). Audio (TTS, STT, voice cloning) and embeddings ship as opt-in extras. → Optional extras
Not into the terminal? Rapid-MLX Desktop bundles the same engine inside a one-click Mac app.
See it in action
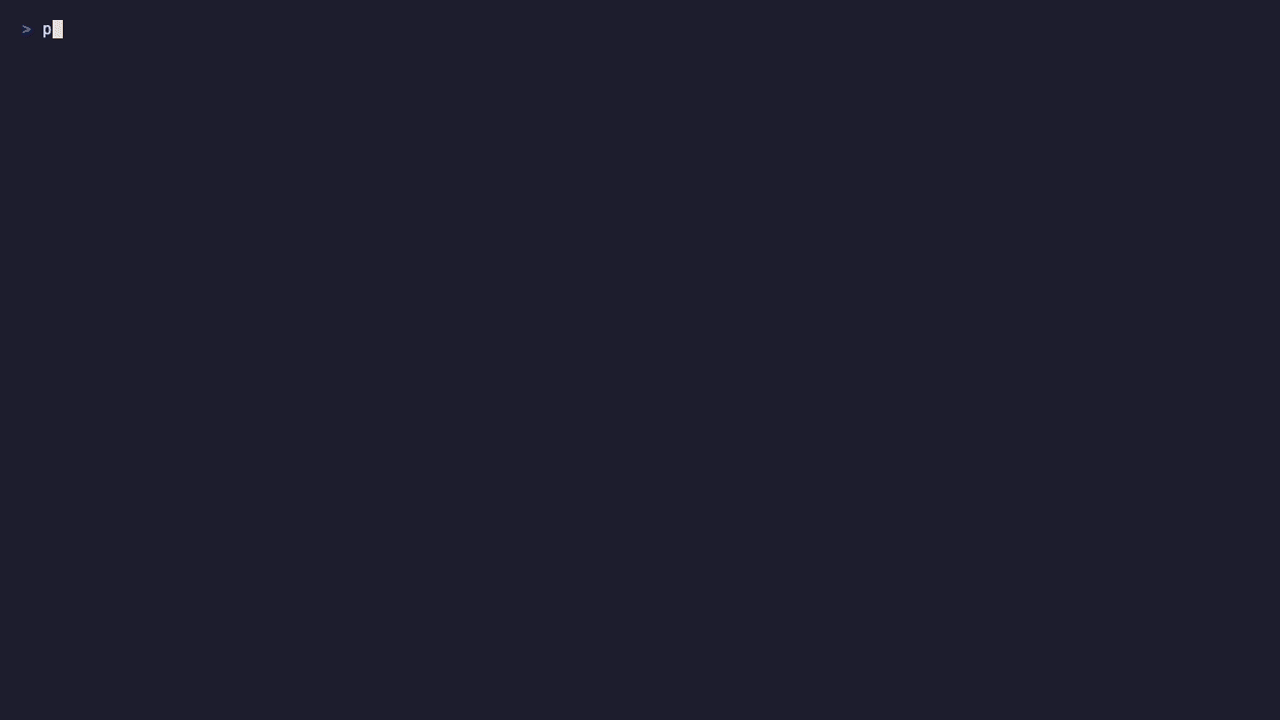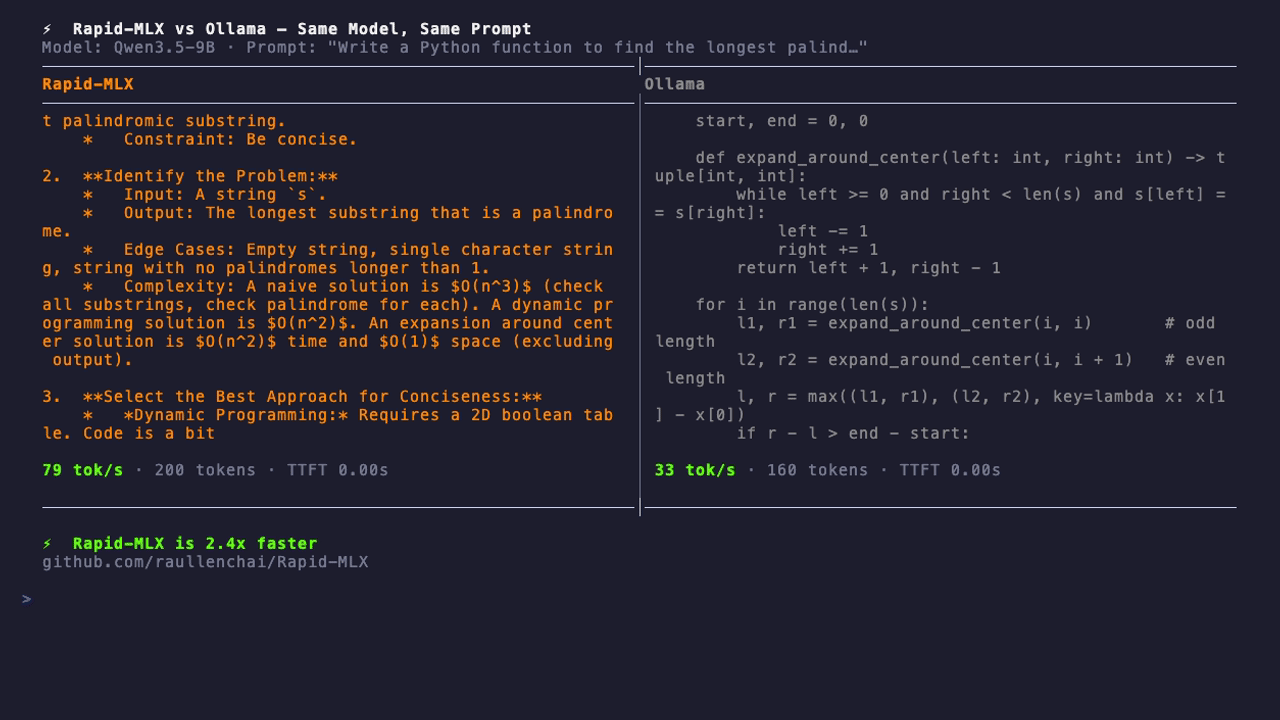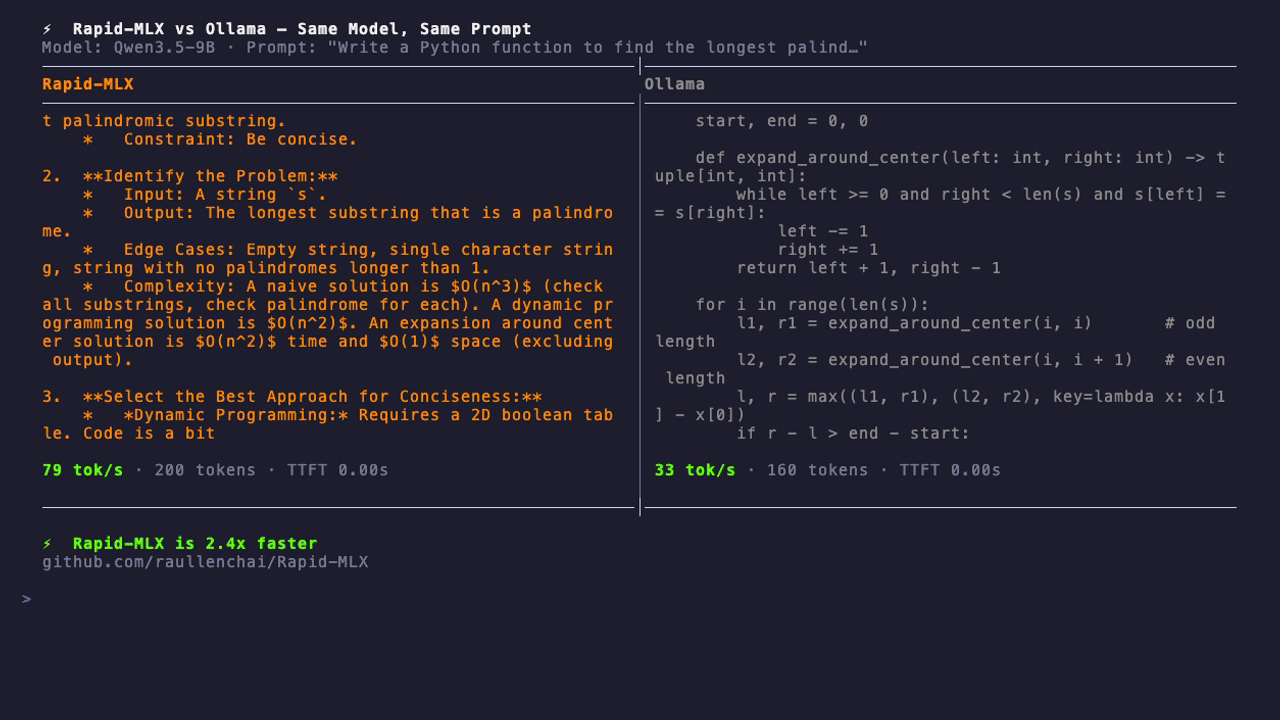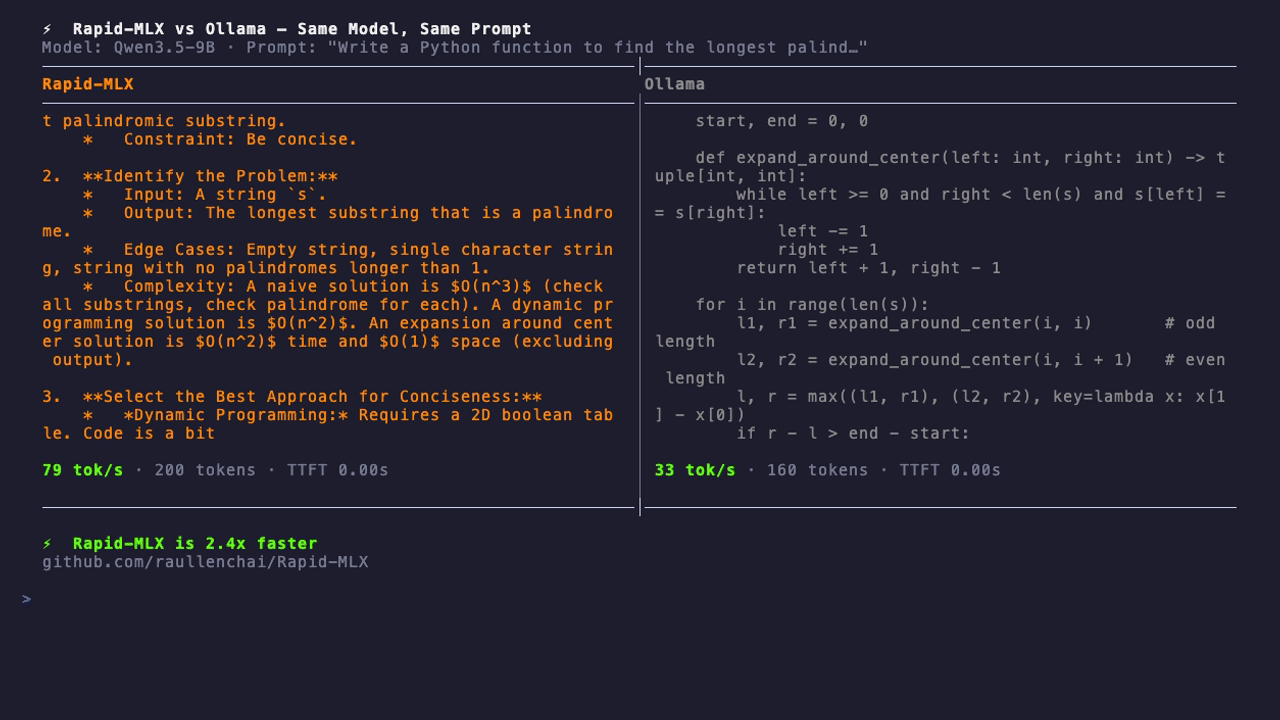
Real session on a Mac mini (M2 Pro, 32 GB), rapid-mlx 0.15.6 from PyPI; idle waits shortened. Recording: docs/assets/demo.cast.
Image generation
Generate images locally from the Desktop Images tab or the OpenAI-compatible Images API. The image runtime ships with the base install (Python 3.11+):
rapid-mlx serve flux2-klein-4b
curl http://localhost:8000/v1/images/generations \
  -H 'Content-Type: application/json' \
  -d '{"model":"flux2-klein-4b","prompt":"A red sailboat on an alpine lake","size":"1024x1024","seed":42}'
Edit an existing PNG or JPEG with the edit-specialized model:
In one terminal:
rapid-mlx serve qwen-image-edit
In another terminal:
curl http://localhost:8000/v1/images/edits \
  -F image=@input.png \
  -F model=qwen-image-edit \
  -F 'prompt=Change the sky to a warm sunset' \
  -F response_format=b64_json
flux2-klein-4b is the recommended starting point. Download sizes are the
currently cataloged model payloads; minimum unified memory includes practical
headroom for macOS and the serving process. Omit steps to use the validated
family default shown below.
| Alias | Best fit | Modes | Download | Minimum unified memory | Default steps |
|---|---|---|---|---|---|
flux2-klein-4b |
Recommended; fast everyday images | Generate + edit | 4.3 GiB | 12 GB | 4 |
bonsai-image-4b-2bit |
Smallest download | Generate | 3.6 GiB | 12 GB | 4 |
z-image-turbo |
Photorealistic images | Generate | 5.5 GiB | 16 GB | 8 |
flux-schnell |
FLUX.1 compatibility | Generate | 9.0 GiB | 16 GB | 4 |
sdxl-base |
SDXL compatibility | Generate | 6.5 GiB | 16 GB | 30 |
flux2-klein-4b-bf16 |
Explicit full-precision Klein path | Generate + edit | 14.9 GiB | 32 GB | 4 |
hidream-o1-dev |
Complex compositions | Generate | 16.4 GiB | 32 GB | 28 |
sd35-large-4bit |
Stable Diffusion 3.5 | Generate | 15.3 GiB | 32 GB | 28 |
qwen-image-2.1 |
Text-rich images on low-memory Macs | Generate + edit | 8.9 GiB | 8 GB | 40 |
qwen-image |
Same model as qwen-image-2.1 |
Generate + edit | 8.9 GiB | 8 GB | 40 |
qwen-image-2.1-bf16 |
Higher-precision Qwen Image 2.1 path | Generate + edit | 30.9 GiB | 32 GB | 40 |
qwen-image-2.1-turbo |
Eight-step distilled Qwen Image 2.1 | Generate | 30.2 GiB | 32 GB | 8 |
qwen-image-edit |
Precise instruction edits and text changes | Edit | 34.9 GiB | 96 GB | 20 |
qwen-image-2.1 uses mflux 0.20 with a native MLX q4 transfor