SWE-AF
Autonomous Engineering Team Runtime Built on AgentField
Pronounced: "swee-AF" (one word)
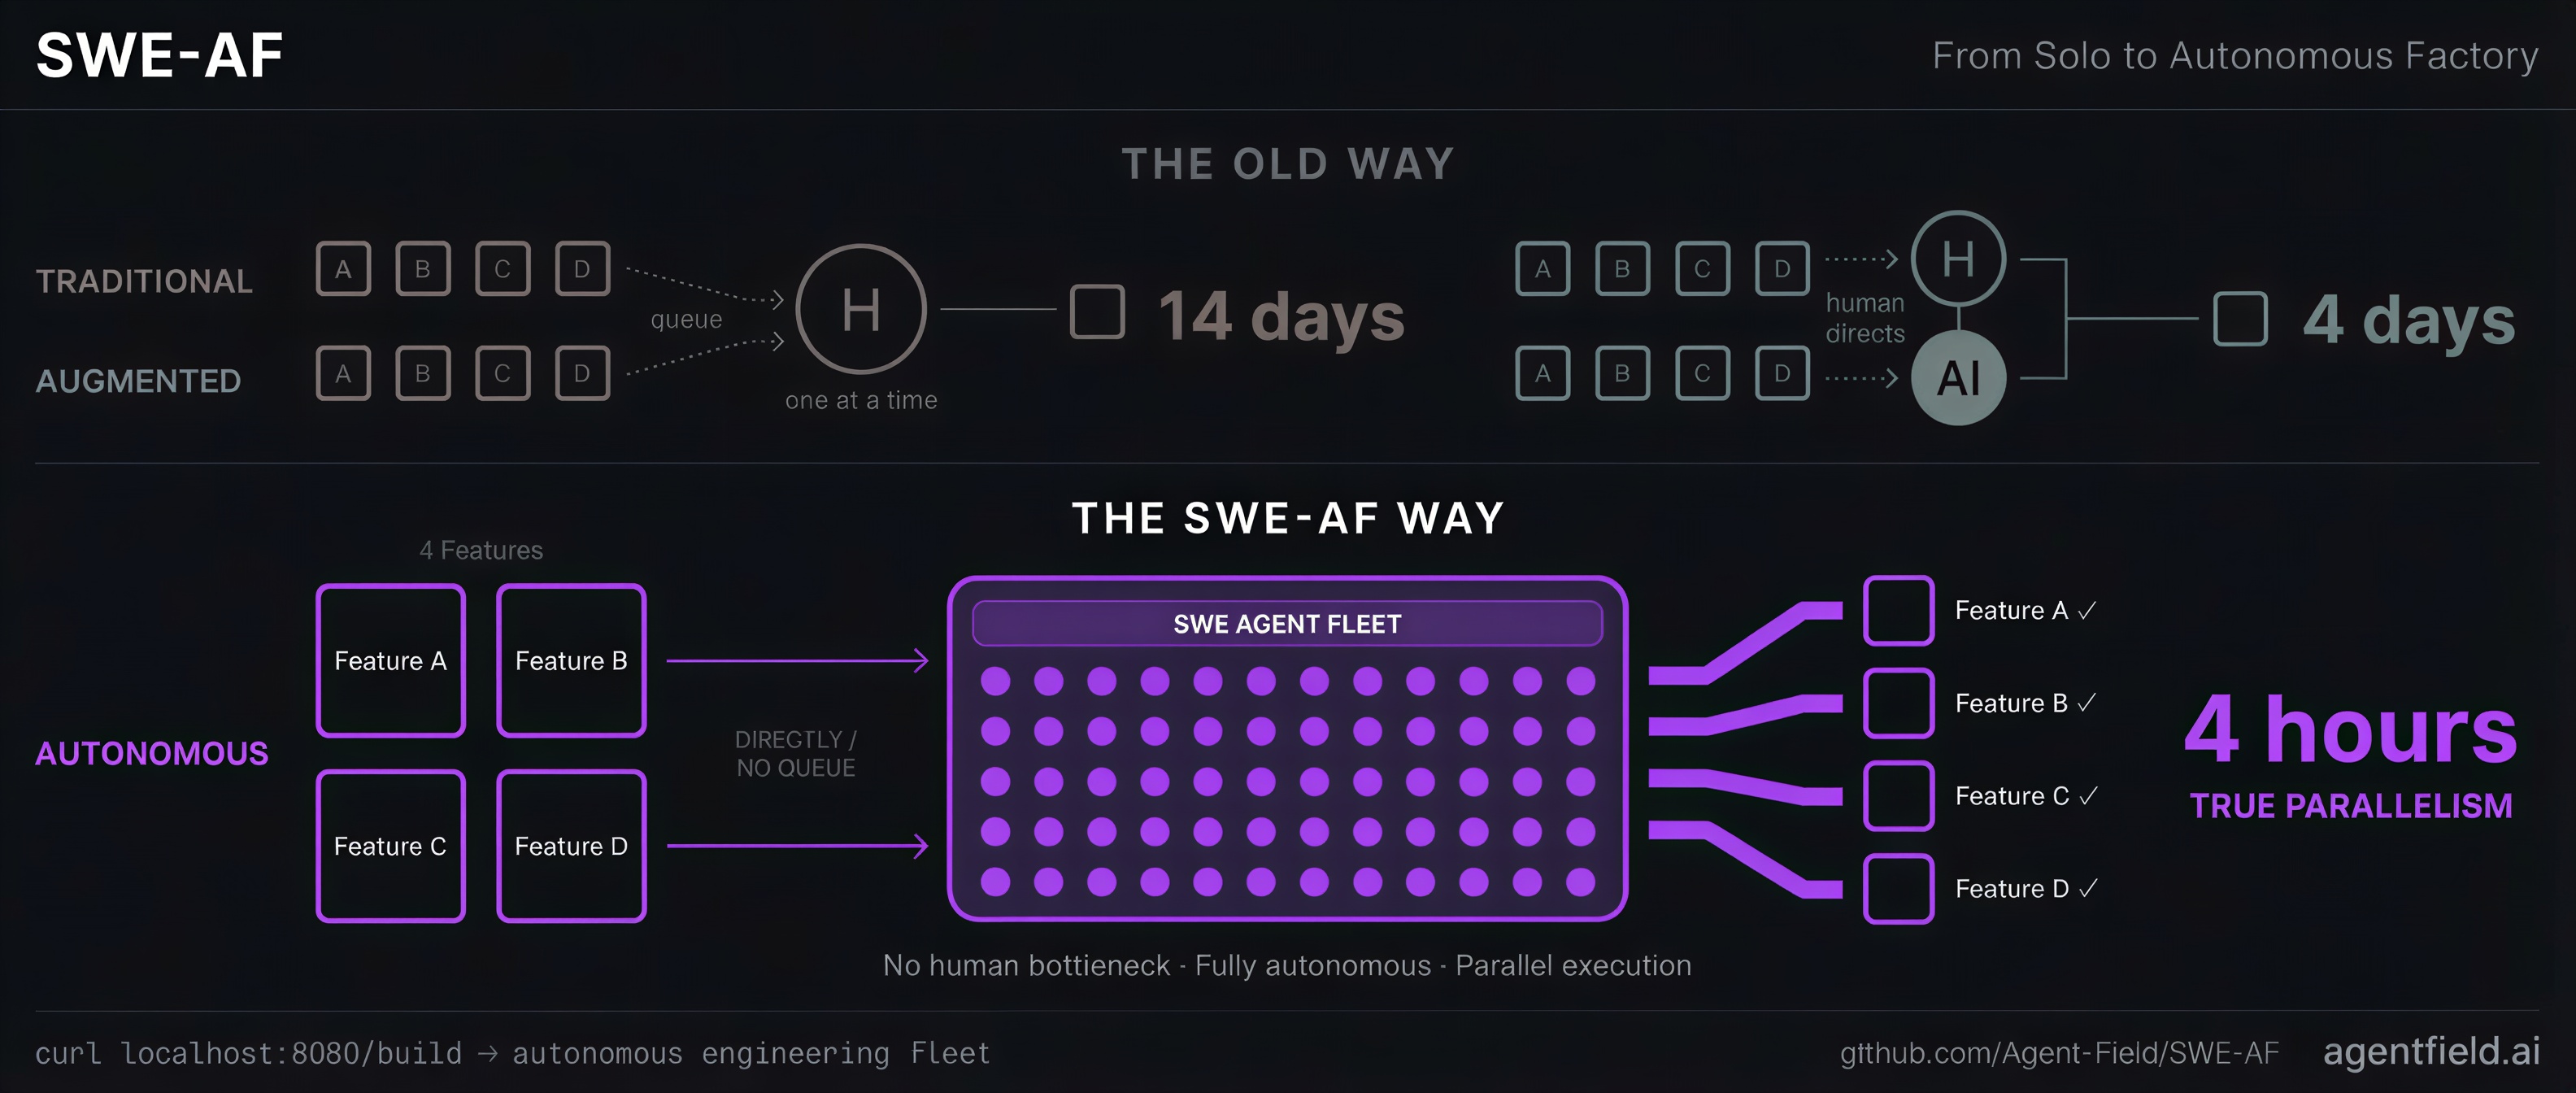
One API call → full engineering team → shipped code.
Quick Start • Why SWE-AF • In Action • Factory Control • Benchmark • Modes • API • Architecture
One API call spins up a full autonomous engineering team — product managers, architects, coders, reviewers, testers — that scopes, builds, adapts, and ships complex software end to end. SWE-AF is a first step toward autonomous software engineering factories, scaling from simple goals to hard multi-issue programs with hundreds to thousands of agent invocations.
One-Call DX
Trigger it with the af CLI (requires af ≥ 0.1.87) — it streams live progress and prints the result:
af call swe-planner.build --in '{
  "goal": "Refactor and harden auth + billing flows",
  "repo_url": "https://github.com/user/my-project",
  "config": {
    "runtime": "claude_code",
    "models": { "default": "sonnet", "coder": "opus", "qa": "opus" },
    "enable_learning": true
  }
}'
Prefer raw HTTP? Hit the API directly with curl:
curl -X POST http://localhost:8080/api/v1/execute/async/swe-planner.build \
  -H "Content-Type: application/json" \
  -d @- <<'JSON'
{
  "input": {
    "goal": "Refactor and harden auth + billing flows",
    "repo_url": "https://github.com/user/my-project",
    "config": {
      "runtime": "claude_code",
      "models": {
        "default": "sonnet",
        "coder": "opus",
        "qa": "opus"
      },
      "enable_learning": true
    }
  }
}
JSON
Swap models.default and any role key (coder, qa, architect, etc.) to any model your runtime supports.
Operating Modes
SWE-AF works in two modes: point it at a single repository, or orchestrate coordinated changes across multiple repos in one build.
Single-Repository Mode
The default. Pass repo_url (remote) or repo_path (local) and SWE-AF handles everything:
curl -X POST http://localhost:8080/api/v1/execute/async/swe-planner.build \
  -H "Content-Type: application/json" \
  -d '{
    "input": {
      "goal": "Add JWT auth",
      "repo_url": "https://github.com/user/my-project"
    }
  }'
Multi-Repository Mode
When your work spans multiple codebases — a primary app plus shared libraries, monorepo sub-projects, or dependent microservices — pass config.repos as an array with roles:
curl -X POST http://localhost:8080/api/v1/execute/async/swe-planner.build \
  -H "Content-Type: application/json" \
  -d '{
    "input": {
      "goal": "Add JWT auth across API and shared-lib",
      "config": {
        "repos": [
          {
            "repo_url": "https://github.com/org/main-app",
            "role": "primary"
          },
          {
            "repo_url": "https://github.com/org/shared-lib",
            "role": "dependency"
          }
        ],
        "runtime": "claude_code",
        "models": {
          "default": "sonnet"
        }
      }
    }
  }'
Roles:
primary— The main application. Changes here drive the build; failures block progress.dependency— Libraries or services modified to support the primary repo. Failures are captured but don't block.
Use cases:
- Primary app + shared SDK or utilities library
- Monorepo sub-projects that live in separate repos
- Feature spanning multiple microservices (e.g., API + worker queue)
Autonomous Build Spotlight
Rust-based Python compiler benchmark (built autonomously):
| Metric | CPython (subprocess) | RustPython (SWE-AF) | Improvement |
|---|---|---|---|
| Steady-state execution | Baseline (~19ms) | Optimized in-process runtime | 88.3x-602.3x faster |
| Geometric mean | 1.0x baseline | 253.8x | 253.8x |
| Peak throughput | ~52 ops/s | 31,807 ops/s | ~612x |
Measurement methodology
Throughput comparison measures different execution models: CPython subprocess spawn (~19ms per call → ~52 ops/s) vs RustPython pre-warmed interpreter pool (in-process). This is the real-world tradeoff the system was built to optimize — replacing repeated subprocess invocations with a persistent pool for short-snippet execution.
Artifact trail includes 175 tracked autonomous agents across planning, coding, review, merge, and verification.
Details: examples/llm-rust-python-compiler-sonnet/README.md
Why SWE-AF
Most agent frameworks wrap a single coder loop. SWE-AF is a coordinated engineering factory — planning, execution, and governance agents run as a control stack that adapts in real time.
- Hardness-aware execution — easy issues pass through quickly, while hard issues trigger deeper adaptation and DAG-level replanning instead of blind retries.
- Factory architecture — not a single-agent wrapper. Planning, execution, and governance agents run as a coordinated control stack — the architecture encodes the engineering strategy, not the prompts (see The Atomic Unit of Intelligence).
- Multi-model, multi-provider — assign different models per role (
coder: opus,qa: haiku). Works with Claude, OpenRouter, OpenAI, and Google. - Continual learning — with
enable_learning=true, conventions and failure patterns discovered early are injected into downstream issues. - Agent-scale parallelism — dependency-level scheduling + isolated git worktrees allow large fan-out without branch collisions.
- Fleet-scale orchestration — many SWE-AF nodes can run continuously in parallel via AgentField, driving thousands of agent invocations across concurrent builds.
- Explicit compromise tracking — when scope is relaxed, debt is typed, severity-rated, and propagated.
- Long-run reliability — checkpointed execution supports
resume_buildafter crashes or interruptions.
In Action
PR #179: Go SDK DID/VC Registration — built entirely by SWE-AF (Claude runtime with haiku-class models). One API call, zero human code.
| Metric | Value |
|---|---|
| Issues completed | 10/10 |
| Tests passing | 217 |
| Acceptance criteria | 34/34 |
| Agent invocations | 79 |
| Model | claude-haiku-4-5 |
| Total cost | $19.23 |
Cost breakdown by agent role
| Role | Cost | % |
|---|---|---|
| Coder | $5.88 | 30.6% |
| Code Reviewer | $3.48 | 18.1% |
| QA | $1.78 | 9.2% |
| GitHub PR | $1.66 | 8.6% |
| Integration Tester | $1.59 | 8.3% |
| Merger | $1.22 | 6.3% |
| Workspace Ops | $1.77 | 9.2% |
| Planning (PM + Arch + TL + Sprint) | $0.79 | 4.1% |
| Verifier + Finalize | $0.34 | 1.8% |
| Synthesizer | $0.05 | 0.2% |
79 invocations, 2,070 conversation turns. Planning agents scope and decompose; coders work in parallel isolated worktrees; reviewers and QA validate each issue; merger integrates branches; verifier checks acceptance criteria against the PRD.
AForge, Claude, OpenCode, Codex, and Command Code runtimes supported: Run builds with any runtime and tune models per role in one flat config map.
runtime: "aforge"maps to AForge exec and is the default when an OpenRouter key is present without a runtime override.runtime: "claude_code"maps to Claude backend.runtime: "open_code"maps to OpenCode backend (OpenRouter/OpenAI/Google/Anthropic model IDs).runtime: "codex"maps to the OpenAI Codex CLI backend.runtime: "command_code"maps to the Command Code CLI backend (command-code -p, headless) on the Python node. No model ids are baked in: withoutmodels, Command Code's own default model is used, and any id it supports passes through verbatim. The Go node does not support this runtime.
Adaptive Factory Control
SWE-AF uses three nested control loops to adapt to task difficulty in real time:
| Loop | Scope | Trigger | Action |
|---|---|---|---|
| Inner loop | Single issue | QA/review fails | Coder retries with feedback |
| Middle loop | Single issue | Inner loop exhausted | run_issue_advisor retries with a new approach, splits work, or accepts with debt |
| Outer loop | Remaining DAG | Escalated failures | run_replanner restructures remaining issues and dependencies |
This is the core factory-control behavior: control agents supervise worker agents and continuously reshape the plan as reality changes.
Quick Start
Install into AgentField (af install)
Already running an AgentField control plane? Install SWE-AF straight from GitHub — no clone, no local Python setup:
af install https://github.com/Agent-Field/SWE-AF
af run swe-planner
af install clones the repo, provisions an isolated Python environment, and registers the swe-planner node with your control plane. On first af run you're prompted for the one required secret — an LLM provider key (ANTHROPIC_API_KEY or OPENROUTER_API_KEY) — which is stored encrypted and reused across every node, so you enter it only once. (Add GH_TOKEN when you want builds to clone private repos and open pull requests.) Then kick off a build:
af call swe-planner.build --in '{"goal": "Add JWT auth", "repo_url": "https://github.com/user/my-repo"}'
New to AgentField? Install the control plane first with curl -fsSL https://agentfield.ai/install.sh | bash, or use the Railway / local options below.
Deploy with Railway (fastest)

One click deploys SWE-AF + AgentField control plane + PostgreSQL. Exactly one environment variable is required in Railway — an LLM provider key:
OPENROUTER_API_KEY— recommended, simplest. One key, 200+ open and proprietary models. When present and no runtime is explicitly selected, SWE-AF uses AForgeexecand defaults every role toopenrouter/deepseek/deepseek-v4-flash-0731.- Alternative:
ANTHROPIC_API_KEY, orCLAUDE_CODE_OAUTH_TOKENfromclaude setup-tokenin Claude Code CLI (uses Pro/Max subscription credits), to run theclaude_coderuntime instead.
Optional:
GH_TOKEN— GitHub personal access token withreposcope. Needed only to clone private repos, push branches, and open pull requests; builds against public repos work without it.
Once deployed, trigger a build:
curl -X POST https://<control-plane>.up.railway.app/api/v1/execute/async/swe-planner.build \
  -H "Content-Type: application/json" \
  -H "X-API-Key: this-is-a-secret" \
  -d '{"input": {"goal": "Add JWT auth", "repo_url": "https://github.com/user/my-repo"}}'
1. Requirements (local)
- Python 3.12+
- AgentField control plane (
af) - AI provider API key (Anthropic, OpenRouter, OpenAI, or Google)
2. Install
python3.12 -m venv .venv
source .venv/bin/activate
python -m pip install --upgrade pip
python -m pip install -e ".[dev]"
3. Run
Harness selection
The Docker image ships AForge: a dedicated build stage downloads the released
binary from https://agentfield.ai/downloads/aforge/<version>/ and verifies it
against the release checksums.txt before it enters the image. Both
coordinates are build args, so a mirror or a different release can be
substituted without editing the Dockerfile:
docker build \
  --build-arg AFORGE_BASE_URL=https://agentfield.ai/downloads/aforge \
  --build-arg AFORGE_VERSION=v0.1.0 \
  -t swe-af .
AFORGE_VERSION is part of that layer's cache key — bumping it is what pulls a
newer AForge; a floating URL alone would keep restoring the cached binary.
A host installation needs aforge on PATH instead:
export OPENROUTER_API_KEY=sk-or-v1-...
export SWE_DEFAULT_RUNTIME=aforge
export SWE_DEFAULT_MODEL=openrouter/deepseek/deepseek-v4-flash-0731
python -m swe_af
Set SWE_DEFAULT_RUNTIME=open_code for an OpenCode rollback (OpenCode stays
installed in the image), or claude_code for Claude.
AFORGE_BINandAGENTFIELD_AFORGE_COMMANDare honored on the pinnedagentfield>=0.1.130SDK, which carries agentfield#905:AFORGE_BINoverrides the binary otherwise resolved asaforgefromPATH, andAGENTFIELD_AFORGE_COMMANDpicks the headless command (exec, the default, ordo) —aforge exec --json -w <root> --timeout <seconds>.
af                 # starts AgentField control plane on :8080
python -m swe_af   # registers node id "swe-planner"
4. Trigger a build
# Default (AForge with OpenRouter; otherwise follows deployment configuration)
curl -X POST http://localhost:8080/api/v1/execute/async/swe-planner.build \
  -H "Content-Type: application/json" \
  -d @- <<'JSON'
{
  "input": {
    "goal": "Add JWT auth to all API endpoints",
    "repo_url": "https://github.com/user/my-project"
  }
}
JSON

# With open-source runtime + flat role map
curl -X POST http://localhost:8080/api/v1/execute/async/swe-planner.build \
  -H "Content-Type: application/json" \
  -d @- <<'JSON'
{
  "input": {
    "goal": "Add JWT auth",
    "repo_url": "https://github.com/user/my-project",
    "config": {
      "runtime": "open_code",
      "models": {
        "default": "openrouter/minimax/minimax-m2.5"
      }
    }
  }
}
JSON

# With Codex CLI runtime
curl -X POST http://localhost:8080/api/v1/execute/async/swe-planner.build \
  -H "Content-Type: application/json" \
  -d @- <<'JSON'
{
  "input": {
    "goal": "Add JWT auth",
    "repo_url": "https://github.com/user/my-project",
    "config": {
      "runtime": "codex",
      "models": {
        "default": "gpt-5.3-codex"
      }
    }
  }
}
JSON

# Fast mode with Codex CLI runtime
curl -X POST http://localhost:8080/api/v1/execute/async/swe-fast.build \
  -H "Content-Type: application/json" \
  -d @- <<'JSON'
{
  "input": {
    "goal": "Add a focused bug fix",
    "repo_url": "https://github.com/user/my-project",
    "config": {
      "runtime": "codex",
      "models": {
        "default": "gpt-5.3-codex"
      }
    }
  }
}
JSON

# Local workspace mode (repo_path) + targeted role override
curl -X POST http://localhost:8080/api/v1/execute/async/swe-planner.build \
  -H "Content-Type: application/json" \
  -d @- <<'JSON'
{
  "input": {
    "goal": "Refactor and harden auth + billing flows",
    "repo_path": "/path/to/repo",
    "config": {
      "runtime": "claude_code",
      "models": {
        "default": "sonnet",
        "coder": "opus",
        "qa": "opus"
      },
      "enable_learning": true
    }
  }
}
JSON
For OpenRouter with open_code, use model IDs in openrouter/<provider>/<model> format (for example openrouter/minimax/minimax-m2.5).
For Infron with open_code, set INFRON_API_KEY and use infron/<provider>/<model> (for example infron/moonshotai/kimi-k2.6). Infron is an OpenAI-compatible gateway serving the standard <provider>/<model> ids, so moving a role across is a prefix swap and nothing else changes:
SWE_DEFAULT_MODEL=infron/moonshotai/kimi-k2.6
With only an INFRON_API_KEY set (no ANTHROPIC_API_KEY, no other gateway key, no SWE_DEFAULT_RUNTIME), the main build/execute/issue/planning paths auto-select the open_code runtime and default to infron/deepseek/deepseek-v4-flash-0731. Fast mode retains its Claude fallback without OpenRouter; select SWE_DEFAULT_RUNTIME=open_code explicitly for fast Infron builds. A gateway key already configured keeps precedence, so adding an Infron key never reroutes an existing deployment on its own.
Docker and Railway deployments using Infron must set
HARNESS_MODEL=infron/deepseek/deepseek-v4-flash-0731(or anotherinfron/...id) in the environment. The image bakes anopenrouter/...value that theopen_codemodel cascade reads after the Infron auto default and would otherwise override it.SWE_DEFAULT_MODELpins every role model but does not feed OpenCode'ssmall_model; setHARNESS_MODELfor that path (setting both is fine).
MiniMax direct providers
The Docker images include direct MiniMax provider entries for both supported regions and API compatibility modes. Every entry lists MiniMax-M3.1-Flash first, followed by MiniMax-M3. Set the model explicitly with the environment variables below; existing runtime and per-role overrides still apply.
| Region | OpenAI-compatible open_code model IDs |
Anthropic-compatible open_code model IDs |
Anthropic base URL |
|---|---|---|---|
| Global | minimax-global-openai/MiniMax-M3.1-Flash, minimax-global-openai/MiniMax-M3 |
minimax-anthropic/MiniMax-M3.1-Flash, minimax-anthropic/MiniMax-M3 |
https://api.minimax.io/anthropic |
| China | minimax-cn-openai/MiniMax-M3.1-Flash, minimax-cn-openai/MiniMax-M3 |
minimax-anthropic/MiniMax-M3.1-Flash, minimax-anthropic/MiniMax-M3 |
https://api.minimaxi.com/anthropic |
| Model | Context window | Maximum output | Input modalities | Thinking | Input / output / cache read per million tokens |
|---|---|---|---|---|---|
MiniMax-M3.1-Flash |
1,000,000 | 524,288 | text, image, video | always adaptive | $0.15 / $0.60 / $0.015 |
MiniMax-M3 |
1,000,000 | 524,288 | text, image, video | adaptive or disabled | $0.30 / $1.20 / $0.06 |
MiniMax-M3 Standard pricing is tiered by input length: requests over 512K input tokens are billed at $0.60 / $2.40 / $0.12 instead. Priority pricing is 1.5× Standard. The flat provider metadata represents only the Standard ≤512K tier. Cache-write pricing is unspecified and omitted. See the official pricing.
Flash thinking is always adaptive. Its OpenCode presets disable the inherited none and thinking variants and expose low, medium, high, xhigh, and max effort instead, with max as the default. The OpenAI-compatible adapter sends reasoning_effort; the Anthropic-compatible adapter sends output_config.effort. M3 retains OpenCode's existing adaptive/disabled variants without effort settings. Although M3's Anthropic API defaults to disabled thinking, OpenCode enables adaptive th