Hydra ETL
Your data pipelines are described, not programmed.
Website · Video tutorials · Docs & playground · MCP server · VS Code extension · Changelog
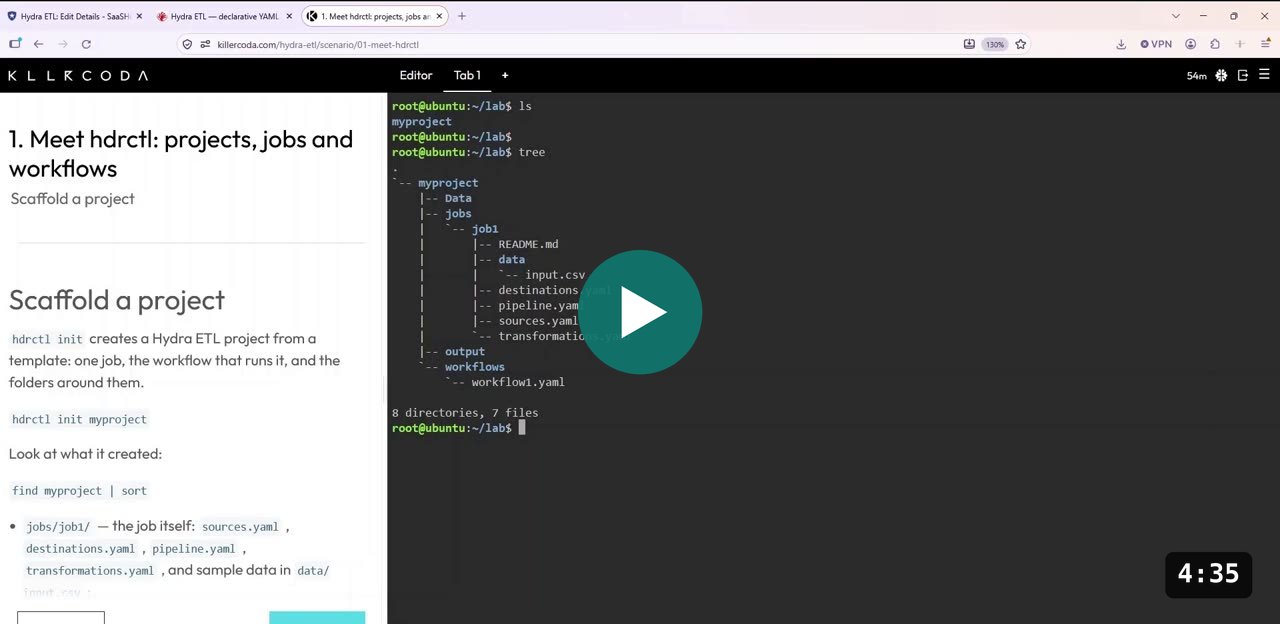
▶ Watch (4:35): create a project with hdrctl init and explore its structure. More videos in Hydra Academy.
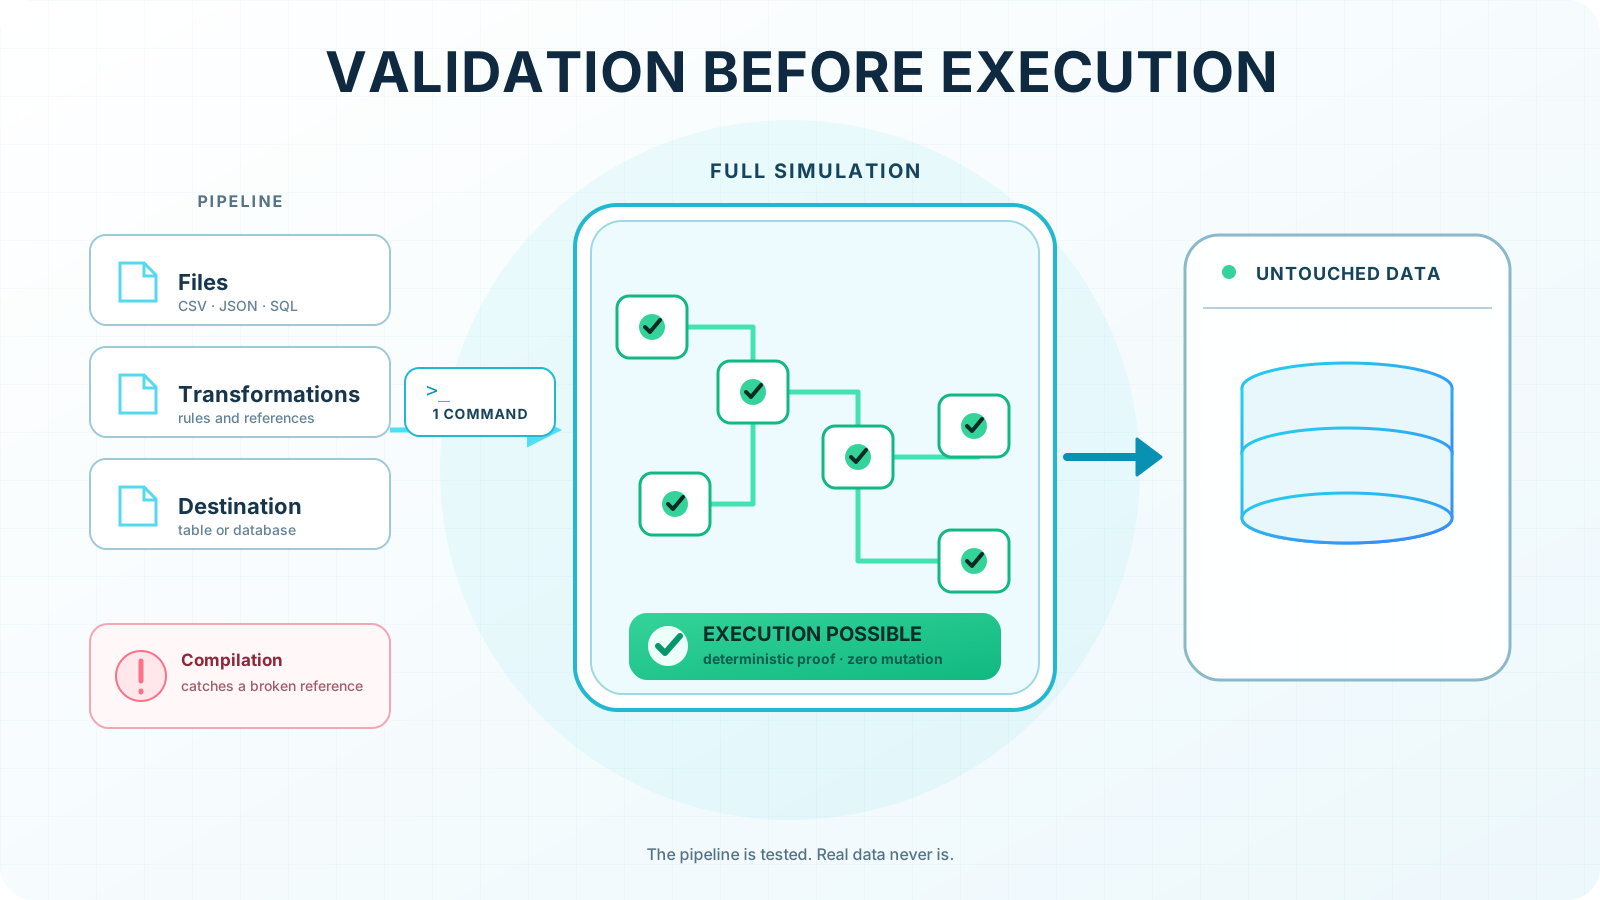
Hydra is an open-source declarative ETL engine. You write what a pipeline is in YAML;
Hydra validates it before touching any data, then runs it. The same manifests run from
the terminal, a REST API, or a visual editor in your browser, with one pip install and nothing else to deploy.
Try it without installing anything
Two sandboxes run Hydra in your browser. Nothing is installed on your machine, and nothing is left behind when you close the tab.
Guided labs — no account needed
Killercoda gives you a Linux terminal inside your browser, next to a short lesson that tells you exactly what to type. Each lab takes ten to fifteen minutes and checks your work as you go. There is nothing to sign up for.
Start with Meet hdrctl to see what a job is, then Parameters and secrets to run one pipeline against two databases.
A full environment, with the visual editor
GitHub Codespaces starts a real machine in the cloud and opens an editor in your browser. It needs a free GitHub account, and it runs within GitHub's free monthly allowance.
This one comes with a MySQL database already running beside it and a working
pipeline. Once it opens, type ./tour — a five-minute walkthrough that
shows you each command before running it. It is the only thing you have to type.
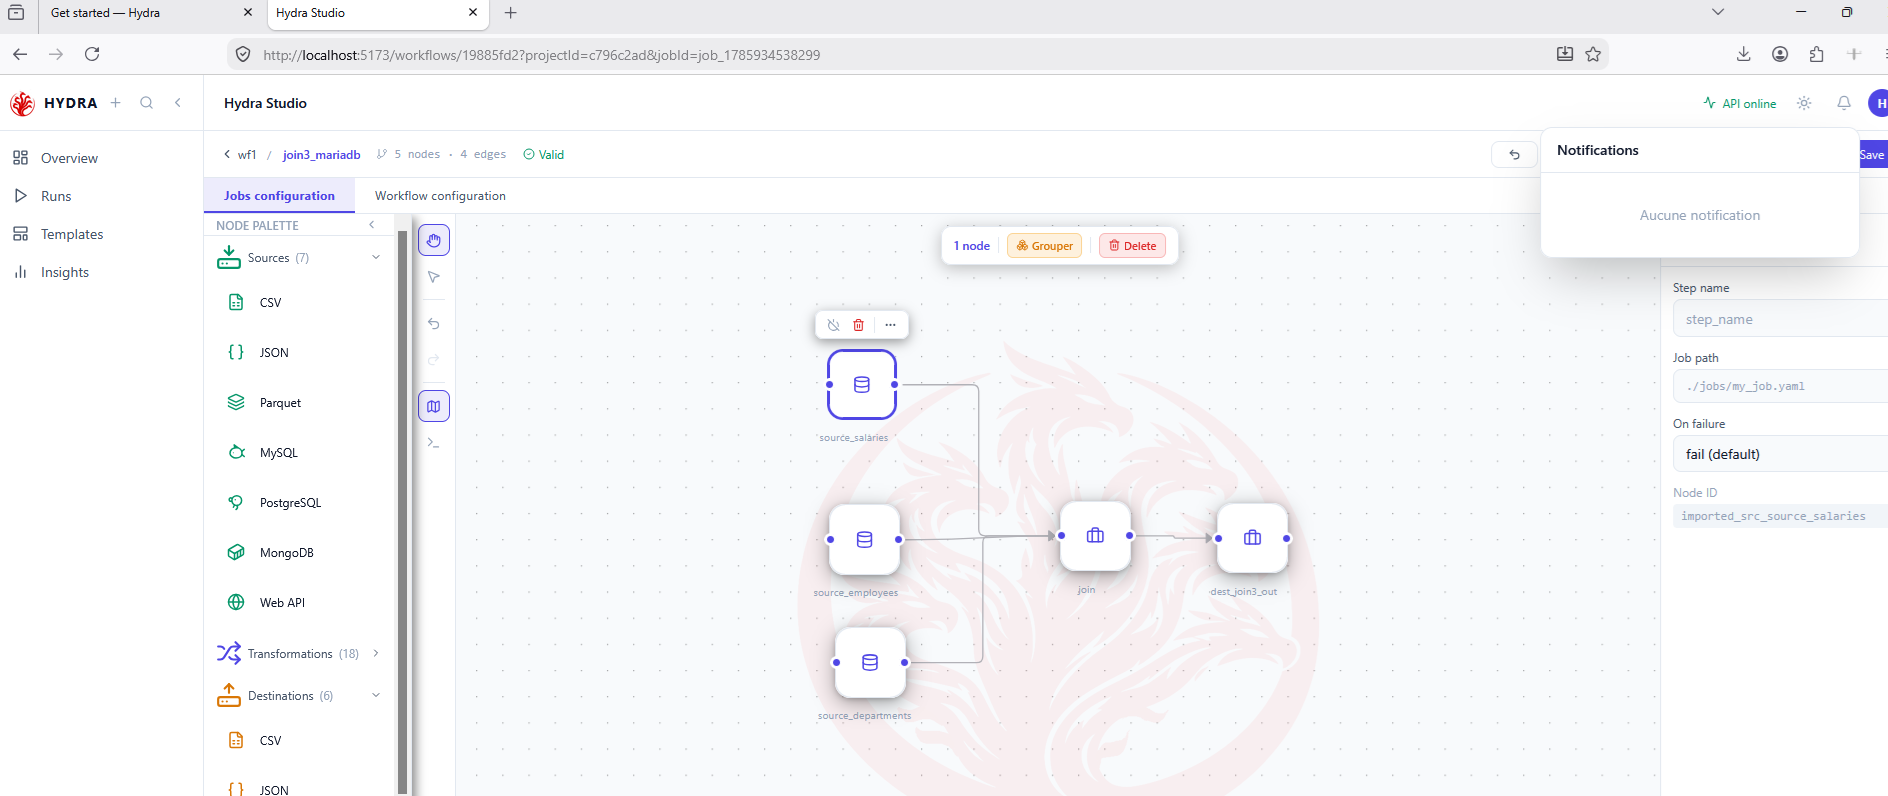
Unlike the labs, this environment includes Hydra Studio, the visual editor, so you can see the same pipeline as a diagram and run it from there.
Quick start
pip install "hydra-etl[server]"
hdrctl serve --open            # Studio + API on http://localhost:5678
Or stay in the terminal:
hdrctl init my_project                 # or `hdrctl init .` in an empty folder
hdrctl run my_project --dry-run        # validate the whole project, run nothing
hdrctl run my_project                  # run every workflow (or `hdrctl run .` from inside)
hdrctl validate my_project/jobs/job1   # strict validation of one job, no data touched
hdrctl run my_project/jobs/job1        # run one job alone
A project is a set of workflows; a workflow is a set of jobs and actions.
init scaffolds a full project:
my_project
├── .gitignore           keeps .hydra/secrets and .env out of git
├── .hydra/              project marker, Studio data, and secrets (name=value, git-ignored)
├── Data/                input data
├── environments/        parameter values per environment (dev.yaml, prod.yaml…)
├── jobs/
│   └── job1/
│       ├── README.md
│       ├── data/input.csv
│       ├── destinations.yaml
│       ├── pipeline.yaml
│       ├── sources.yaml
│       └── transformations.yaml
├── outputs/             files produced by the jobs
├── parameters.yaml      project parameters, used as {{ param:NAME }}
├── README.md
├── scripts/             scripts called by workflow actions
└── workflows/
    ├── thread.yaml      execution order of the workflows
    └── workflow1.yaml
Six job templates are available with --template (basic, csv, mysql, postgres, api,
mongodb). workflows/thread.yaml lists the workflows in stages, each sequential or parallel,
with an optional delay_after, and per workflow an active flag, an optional delay_before and
an optional timeout:
version: "1.0"
thread:
  - mode: sequential
    delay_after: 30s          # optional pause before the next stage
    workflows:
      - name: workflow1
        timeout: 30m          # optional: beyond it, the workflow fails
      - name: workflow2
        active: false         # skipped, without removing it
  - mode: parallel
    workflows:
      - name: export-a
      - name: export-b
        delay_before: 23s     # starts 23 s after the stage (staggered start)
loops:                        # optional
  - from: export-b            # when export-b finishes…
    to: workflow1             # …go back to workflow1
    times: 3                  # 3 passes in total
    delay: 5m                 # optional pause before each repeat
delay_before waits before starting a workflow: in a sequential stage, after the previous
workflow; in a parallel stage, after the stage starts. Same format as delay_after (500ms,
30s, 5m, 1h, or seconds). Fallback conditions are checked after the wait. In a parallel
stage, a failed workflow cancels the starts still waiting.
timeout is the longest a workflow may run (same format, more than 0). Beyond it, the workflow
is stopped at the next step or batch — an all-or-nothing load is cancelled, an action already
started finishes (it has its own timeout) — and counts as failed:
✗ Workflow 'load_crm' failed (30.0s): timed out after 30s. It also applies to each backup run
in its place.
A loop can link any two workflows of the thread (to comes before from, or is the same
workflow); loops must not overlap.
A workflow can declare a fallback: one or more backup workflows, kept outside the thread, that take its place when a condition is true just before the start, or after it fails:
      - name: load_crm
        fallback:
          use: [load_crm_backup]                    # tried in order
          when: "not source_available('crm_db')"    # checked just before the start
          on_failure: true                          # also after a failure
when uses a small closed language (never Python eval): source_available('name'),
destination_available('name'), file_exists('path'), file_size('path'), file_age('path'),
url_ok('url'), secret_defined('name'), db.load('name'), previous.status, previous.rows,
with and, or, not, comparisons, durations (30s, 24h) and sizes (5MB).
hdrctl workflow add load_crm_backup --fallback-for load_crm creates a backup workflow and
declares it. hdrctl run . --dry-run checks the fallbacks (files, jobs, names used by when)
and warns when a backup writes somewhere else than the workflow it replaces.
At run time, when is checked just before the workflow starts. Each check is quick, reads
no data and has a time limit (HYDRA_PROBE_TIMEOUT, 15 s by default). If the condition is
true, the first backup runs in its place (same stage, same loop pass) and the reason is
shown: ↪ Fallback: load_crm → load_crm_backup — source_available('crm_db') = false (connection refused). If a check cannot answer (time limit, missing file for file_size…), the planned
workflow runs (on_probe_error: keep, the default) or the backup does (replace). An inactive
workflow is not checked. hdrctl run . --use-fallback load_crm forces the switch, to rehearse a
recovery.
With on_failure: true, a workflow that fails (or exceeds its timeout) is replaced by its
first backup only if it left nothing published: no load published and no outside action
done (webhook, email, bash, python… except those marked undo: none), or everything
undone by rollback: true. The backup then cannot write the same data twice. If the backup
fails too, the next one in use runs. Otherwise the project stops and says why:
⛔ load_crm: fallback load_crm_backup not started — step 'load1' had already published its data.
hdrctl run . --dry-run warns when a workflow with on_failure publishes in several steps
without rollback: true.
In Studio, Settings › Project settings (button Project settings on the project page)
edits the same file (Execution order → Define), draws it (Preview) and checks it
(Check); the project page keeps the workflows and a Run project button.
The life-buoy button of a workflow edits its fallback: backup workflows (one taken from the
thread leaves it), the when condition, checked as you type, with a helper that inserts a
function and a source or destination of the project, and on_probe_error. Preview draws
each backup as a dashed block under its workflow, with the condition on the link; Check
shows the warnings; the run page tells which workflow ran, the backup or not, and why: a
workflow replaced after a failure shows replaced by …, a stopped one timed out, a blocked
switch fallback blocked with the reason. The max field of a workflow line sets its
timeout (⏳ in the Preview).
The wait field of each workflow line sets its delay_before; Preview shows it as a
clock above the block and the run page as a waited … badge on the step.
hdrctl run <project> checks the thread, every active workflow and the job folders they use
before starting anything, then runs the stages in order. A failed workflow stops the project;
in a parallel stage the workflows already started finish first. Without thread.yaml, every
workflows/*.yaml runs one after the other, in alphabetical order. Parameters come from the
project's parameters.yaml, environments/<env>.yaml (--env) and -P KEY=VALUE, in that
order of precedence. Workflow triggers (schedule, webhook) are ignored by hdrctl run;
they apply under hdrctl serve.
No Node, no build step, no database, no message broker. Python 3.9+ on Linux, macOS or Windows.
Why Hydra
- Validate before you run.
hdrctl validatechecks sources, steps, types and destinations deterministically, before any data is read or written. - Declarative, visual, zero deployment. YAML manifests, a browser editor that outputs the same YAML, and a single Python process. No cluster, no JVM, no container required.
- Built for CI/CD. Manifests are versioned and reviewed like code;
hdrctlscaffolds, validates, tests and runs from a terminal or a CI job. - Built-in scheduler. DAG workflows with dependencies, parallel branches, delayed retries, cron triggers, conditional guards and eleven actions (webhook, email, Bash, PowerShell, SSH, Python…).
- One job, many environments.
{{ param: }},{{ env: }}and${SECRET:}keep the manifest identical across dev, staging and production. - Two engines per operation. pandas or DuckDB, chosen step by step, with optional Rust acceleration (see Native acceleration).
- AI-ready. An MCP server lets Claude, Cursor or VS Code write pipelines that Hydra validates.

How it compares
| Hydra | Airflow | dbt | Airbyte | NiFi / Apache Hop | |
|---|---|---|---|---|---|
| Pipelines defined in | YAML | Python | SQL + YAML | UI / config | UI flows |
| Scope | Extract, transform, load | Orchestration | Transform in the warehouse | Extract & load | Extract, transform, load |
| Visual editor | Included | Monitoring UI | Not in dbt Core | Included | Included |
| To get started | pip install |
Scheduler, webserver, metadata DB | A data warehouse | Docker / Kubernetes | JVM |
Hydra is not a replacement for all of these. It targets file-and-database pipelines that should stay readable and run without extra infrastructure.
What you get
| Component | Description |
|---|---|
| Engine | Declarative jobs: one source, N transformations, one destination |
| CLI | hdrctl: scaffold, validate, run, inspect. English and Spanish |
| API | FastAPI, with interactive docs at /docs |
| Studio | Visual editor for jobs and workflows; opens an existing project folder |
| Workflows | Multi-job DAG with dependencies, actions, retries and runtime parameters |
| MCP | Natural-language pipeline authoring, validated by Hydra |
Connectors (sources and destinations):
 CSV |
 JSON |
 Parquet |
 MySQL / MariaDB |
 PostgreSQL |
 SQL Server |
 MongoDB |
 Web API |
|---|
Transformation engines: pandas and DuckDB.
Who it is for
- Data engineers and analysts who need repeatable file-and-database pipelines without standing up infrastructure for them.
- Teams where pipelines must stay readable by people who do not write Python: a YAML manifest reviewed in a pull request, not a script.
- Developers embedding ETL in a product, who want a CLI and a REST API over the same engine.
A job in four files
A job is a folder. Four manifests describe it, and each one answers a single question.
sources.yaml: where the data comes from
version: "1.0"
sources:
  src_input:
    type: csv
    extract:
      table: ./input.csv
transformations.yaml: how it is reshaped
version: "1.0"
steps:
  - cast:
      mapping:
        amount: float
  - filter:
      expr: "amount > 0"
  - aggregate:
      by: [name]
      agg:
        total: { func: sum, col: amount }
A CSV carries no types, so cast comes before any numeric comparison.
destinations.yaml: where it goes
version: "1.0"
destinations:
  dest_output:
    type: csv
    load:
      table: ./output.csv
      mode: replace          # append | replace | upsert
      # atomic: true         # all-or-nothing (see below)
All-or-nothing load. A job writes its destination in one go: nothing is visible before the end, and a failure (or Ctrl+C) leaves the destination as it was. It is on by default where it costs nothing:
| Destination | replace |
append |
upsert |
|---|---|---|---|
| PostgreSQL, SQL Server | one transaction (TRUNCATE inside it) | atomic: true |
atomic: true |
| MySQL / MariaDB | one transaction (DELETE, InnoDB table) | atomic: true |
atomic: true |
| CSV | temporary file, then swapped | back to the original size | — |
| Parquet | temporary file, then swapped | temporary file, then swapped | — |
atomic: true makes append / upsert into a database one transaction too (longer locks, a
larger database log: fine for medium volumes); atomic: false goes back to batch-by-batch
commits. atomic: true where it cannot work (MongoDB, web API, a MyISAM table) is an error,
never a silent downgrade. In PostgreSQL, readers of a table being replaced wait for the end of
the job instead of seeing it empty. Temporary files left by a crashed run are removed on the
next run.
pipeline.yaml: which source feeds which destination
version: "1.0"
pipeline:
  from: src_input
  to: dest_output
hdrctl validate my_job && hdrctl run my_job
Workflows: order several jobs
version: "1.0"
workflow:
  name: daily_etl
  trigger:
    type: schedule
    cron: "0 8 * * *"
  steps:
    - name: extract
      type: job
      job: ./jobs/extract
      depends_on: []

    - name: transform
      type: job
      job: ./jobs/transform
      depends_on: ["extract"]     # always a list, supports fan-in

    - name: notify
      type: action
      action: webhook
      params: { url: "{{ env:WEBHOOK_URL }}" }
      depends_on: ["transform"]
      on_failure: skip
hdrctl workflow add daily_sales        # new empty workflow, added at the end of thread.yaml
hdrctl workflow list                   # workflows in thread order: stage, active/inactive, steps
hdrctl workflow validate daily_sales   # by name inside a project, or by file path
hdrctl workflow run daily_sales        # one workflow
hdrctl workflow remove daily_sales     # deletes the file and its thread entry; jobs are kept
hdrctl run .                           # every workflow, in the order of thread.yaml
Rollback. With rollback: true, a workflow that fails undoes the steps it has already
done, the last one first. Jobs are undone automatically: the previous file comes back (it is
kept next to the new one until the end of the run), a replaced table gets its previous content
back (a copy hydra_bak_… taken before the load), the rows added by append / upsert are
removed and the rows changed by upsert get their old values. Actions that act outside Hydra
(webhook, email, bash, powershell, ssh, python) say how to reverse them:
workflow:
  name: daily_sales
  rollback: true
  steps:
    - name: load
      type: job
      job: ../jobs/load_sales        # database append: load.key is required
    - name: publish
      type: action
      action: bash
      params: { command: "cp outputs/sales