Your CLAUDE.md only grows. Knowl retires facts when they change.
Quick start · Why supersession · What gets stored · Features · Agent setup · Viewer · Requirements · Full reference →
Your agent starts every session blank, so you keep a CLAUDE.md. It only grows. Six months in it
still names the database you migrated off last spring, and now the agent gets both answers.
Knowl is persistent memory for AI agents, for code, research and everyday life, over
MCP or the CLI. When a fact is replaced, the old one is retired
instead of competing with the new one. No API key needed. When Knowl isn't sure the new fact
replaces the old, it leaves both active and hands you the knowl supersede command to say so.
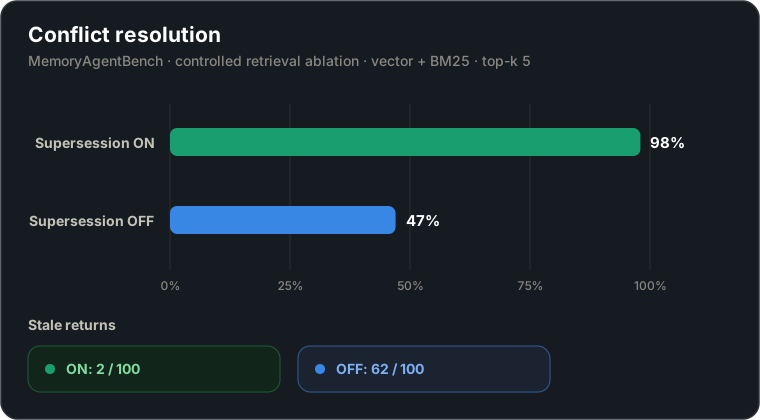
Turn that off and retrieval drops from 98% to 47%. End to end, 90 to 73. How it was measured ↓
Forty seconds, one decision, three agents:
Quick start
Requires Node.js 22 or later. macOS, Linux and Windows.
npm install -g @dat999zx/knowl
cd your-project
knowl init
Other package managers
The published package is the same one in every case; each of these installs it and puts knowl
on your PATH.
pnpm add -g @dat999zx/knowl
yarn global add @dat999zx/knowl
bun add -g @dat999zx/knowl
Or run it without installing:
npx @dat999zx/knowl init
Knowl runs on Node.js in all of these — Bun installs it, Node executes it. It bundles native addons (SQLite, tree-sitter, the embedding runtime), so running the CLI under the Bun or Deno runtime directly is not supported.
knowl init creates .knowl/, installs the project guidance files, updates .gitignore, and
registers Knowl with whichever agents it detects. It also warms a local embedding model (~53 MB)
in the background — init succeeds either way, and without it you still get keyword search.
To refresh every repository and every machine-wide host after an update, run knowl init --all
once. It only upgrades what is already set up: your repositories, the global store if you have one, and
a global instruction block (~/.claude/CLAUDE.md, ~/.codex/AGENTS.md) only where one is already
there. It never creates any of them; knowl init and knowl init --global <host> do that. It replaces
knowl upgrade --all, which still works for one release.
That is the whole setup. You do not record memory by hand: your agent reads and writes it as it works.
Connecting an agent
 Claude Code MCP · lifecycle · gate |
 Codex MCP · lifecycle · gate |
 Hermes MCP · lifecycle · gate |
 OpenClaw in-process · plugin · gate |
 Copilot MCP · lifecycle · gate |
 Cursor MCP · lifecycle · gate |
 OpenHands MCP · lifecycle · gate |
 Antigravity MCP · lifecycle · gate |
 Windsurf MCP · lifecycle · gate |
 Cline MCP · lifecycle · plugin |
 Zed MCP · capture · ACP |
 JetBrains MCP · capture · ACP |
 OpenCode MCP · manual loop |
Claude Desktop MCP · manual loop |
knowl init registers the MCP server for every host it finds. Start a new session afterwards so
the agent picks up its guidance, and it will query and write memory on its own.
gate means Knowl can refuse an edit that invalidates code another session is holding.
Neovim and Kiro work the same way as Zed and JetBrains, through knowl acp. Cline needs one
line pointing it at the shipped plugin. Hermes Agent gets a Python plugin, installed for you,
that works in the terminal and in Hermes Desktop alike; knowl init also selects it as Hermes'
memory provider when none is set, which is what keeps knowl_query out of Hermes' tool search. OpenClaw runs in-process inside its gateway via an extension plugin,
evaluating write gates without subprocess overhead — knowl init openclaw copies it and prints
the two commands that register it. Any other MCP client works with
no integration at all.
Running agents in parallel? Every git worktree resolves to the main checkout's store —
Conductor workspaces, Claude Code's isolation: "worktree", or your
own scripts all share one memory, with nothing to configure.
How that works, and its one limit →
→ Every host, and what each one can do · How agents use it · MCP tools and resources
The idea: memory that retires itself
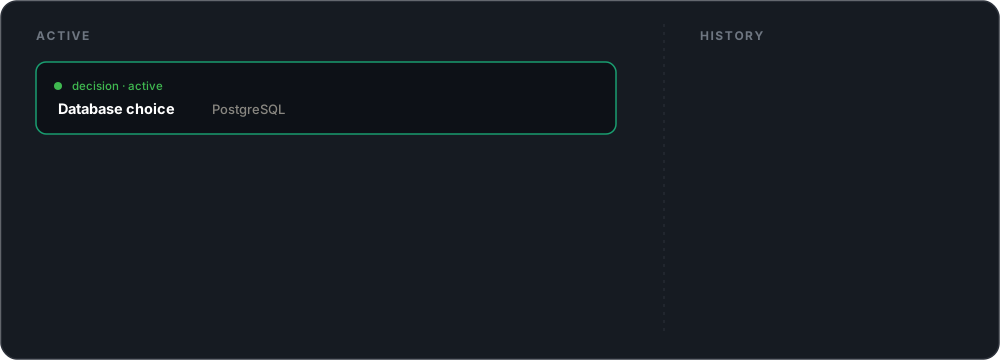
Most memory systems are append-only. Storing "we moved to SQLite" leaves "we use PostgreSQL"
active and retrievable, so the agent gets both and picks by rank. Knowl treats a same-subject write
as a correction: the predecessor is marked superseded, drops out of normal retrieval, and stays
queryable through knowl timeline.
That single behavior is most of the accuracy difference. On the MemoryAgentBench Conflict Resolution corpus — 455 facts, 100 questions about which fact is current, top-5 retrieval, no LLM reader:
| Configuration | Top-1 | Stale returns | Active atoms |
|---|---|---|---|
| Supersession ON | 98.0% | 2 / 100 | 306 |
| Supersession OFF | 47.0% | 62 / 100 | 455 |
Same corpus, same ranker, same query path. The only variable is whether the outdated fact is still active. This is a retrieval-level measurement in Knowl's own harness: it asks whether the current fact comes back first, with no model in the loop.
Verified end-to-end, in the benchmark's own harness
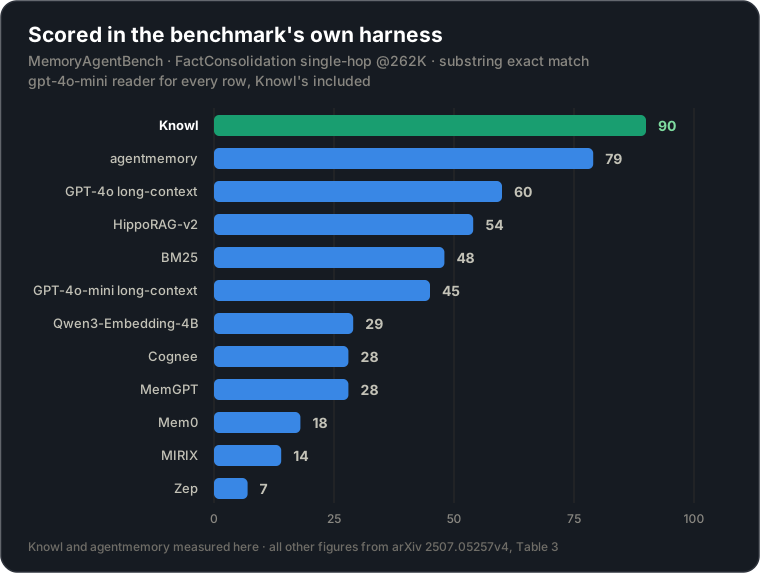
Because a number you score yourself is worth less than one somebody else scores, the same claim was re-run inside MemoryAgentBench's harness, scored by its own code, with an LLM reading what Knowl returned — the harder, fully end-to-end setup, at the largest context the task offers:
| System | FactConsolidation-SH @262K |
|---|---|
| Knowl | 90 |
| agentmemory | 79 |
| GPT-4o (long-context) | 60 |
| HippoRAG-v2 | 54 |
| BM25 | 48 |
| GPT-4o-mini (long-context) | 45 |
| Qwen3-Embedding-4B | 29 |
| Cognee | 28 |
| MemGPT | 28 |
| Mem0 | 18 |
| MIRIX | 14 |
| Zep | 7 |
18,332 facts, 100 questions, substring exact match. Every row uses gpt-4o-mini as the reader, Knowl's included — the paper states it for all RAG and memory agents, so these are like-for-like. Knowl and agentmemory were measured here; every other figure is from the MemoryAgentBench paper, arXiv 2507.05257v4, Table 3. agentmemory is not evaluated in that paper — its published numbers are LongMemEval-S retrieval recall, a different task — so it was run through the same harness with the same config, and both adapters share one reader code path so neither can drift from the paper's own RAG handler. Method, mechanism and reproduction steps: FINDINGS.md.
Otherwise shown are every commercial memory system the paper evaluates, plus the highest scorer from each baseline family. The paper's table has changed between versions — BM25 read 56 in v1 and reads 48 in v4 — so the version is cited, not just the table.
Knowl's 90 was measured 2026-08-08 and independently reproduced at 89.0 on 2026-08-19 with the
checked-in adapter; agentmemory's 79 is a single run. Every figure here is one run at
temperature: 0.7, and the ablation gap moved 4 points between two runs of the same 6k cell, so
read them to the point rather than the decimal.
Switching supersession off in that same harness drops Knowl to 73, and the gap holds across a 40× change in corpus size:
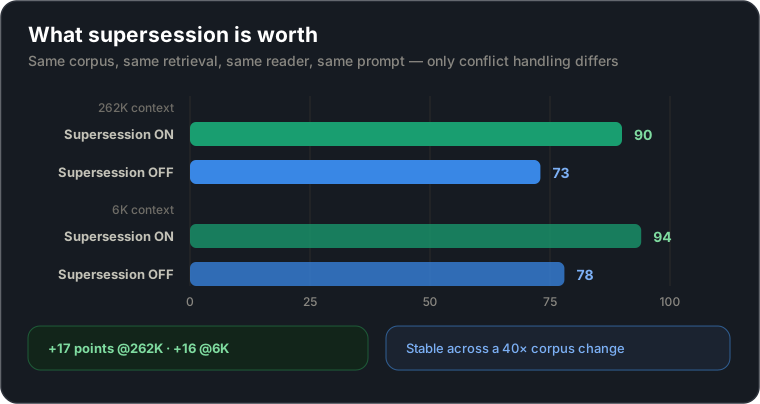
| Context | Supersession ON | OFF | Gap |
|---|---|---|---|
| 262K | 90 | 73 | +17 |
| 6K | 94 | 78 | +16 |
The two sections measure different things and are not comparable to each other: 98% is retrieval top-1 at 6K with no reader, 90 is end-to-end accuracy at 262K with one. Only the second is comparable to the published systems above. See benchmarks for the protocol, the checked-in results, and what the task does not cover — including multi-hop, where Knowl scores 7 against a 14-point retrieval ceiling.
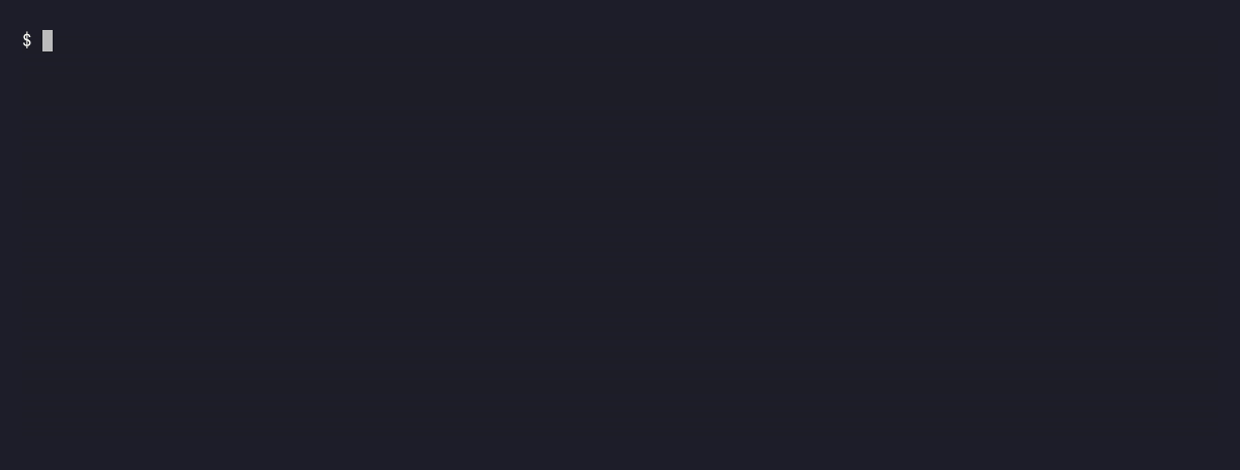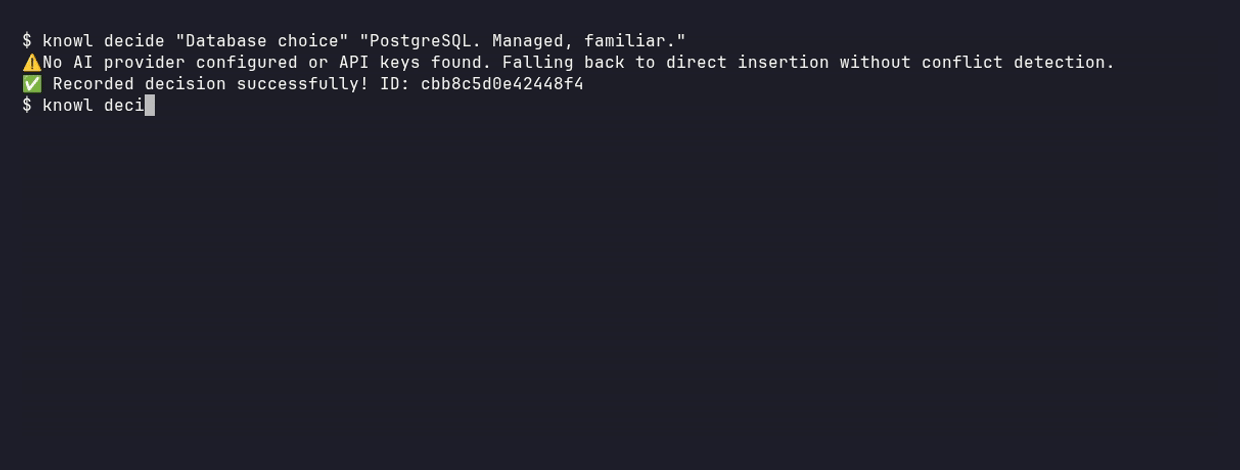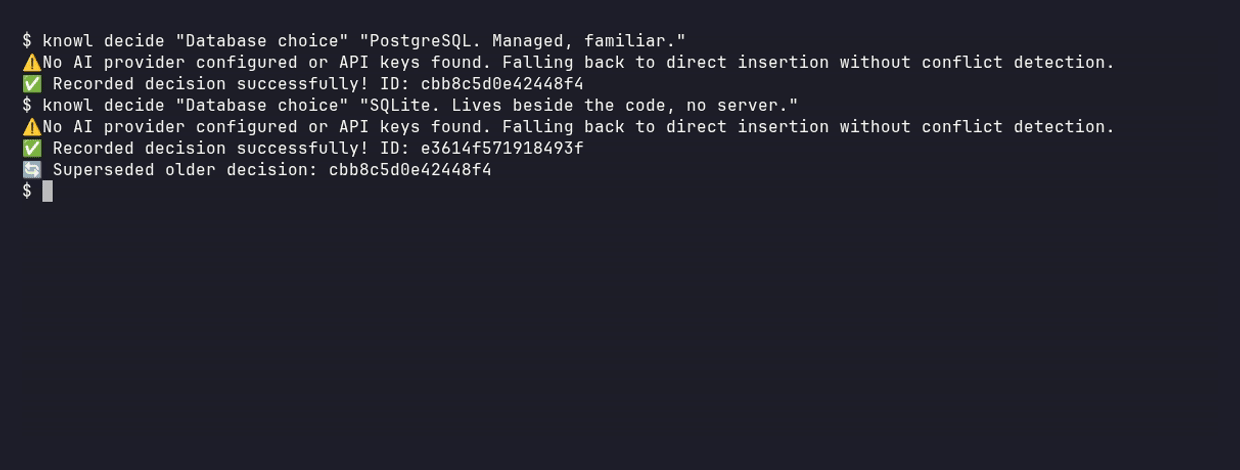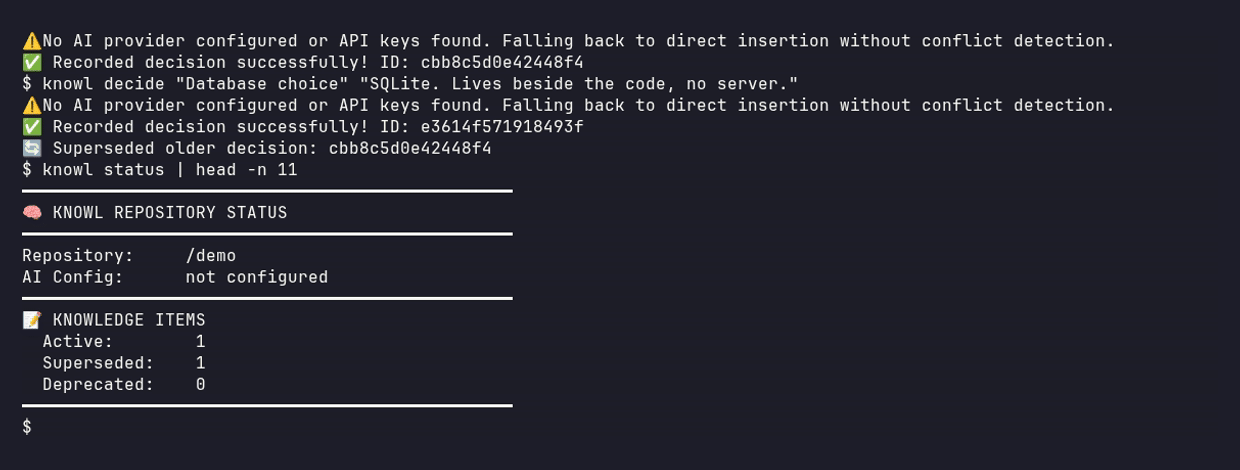
Supersession is a correction, not a delete: the item, its assertions, and its history all survive.
Not a mock-up — the same sequence against the published CLI, recorded from
demo.tape:
Sharing memory across a team: knowl.cloud
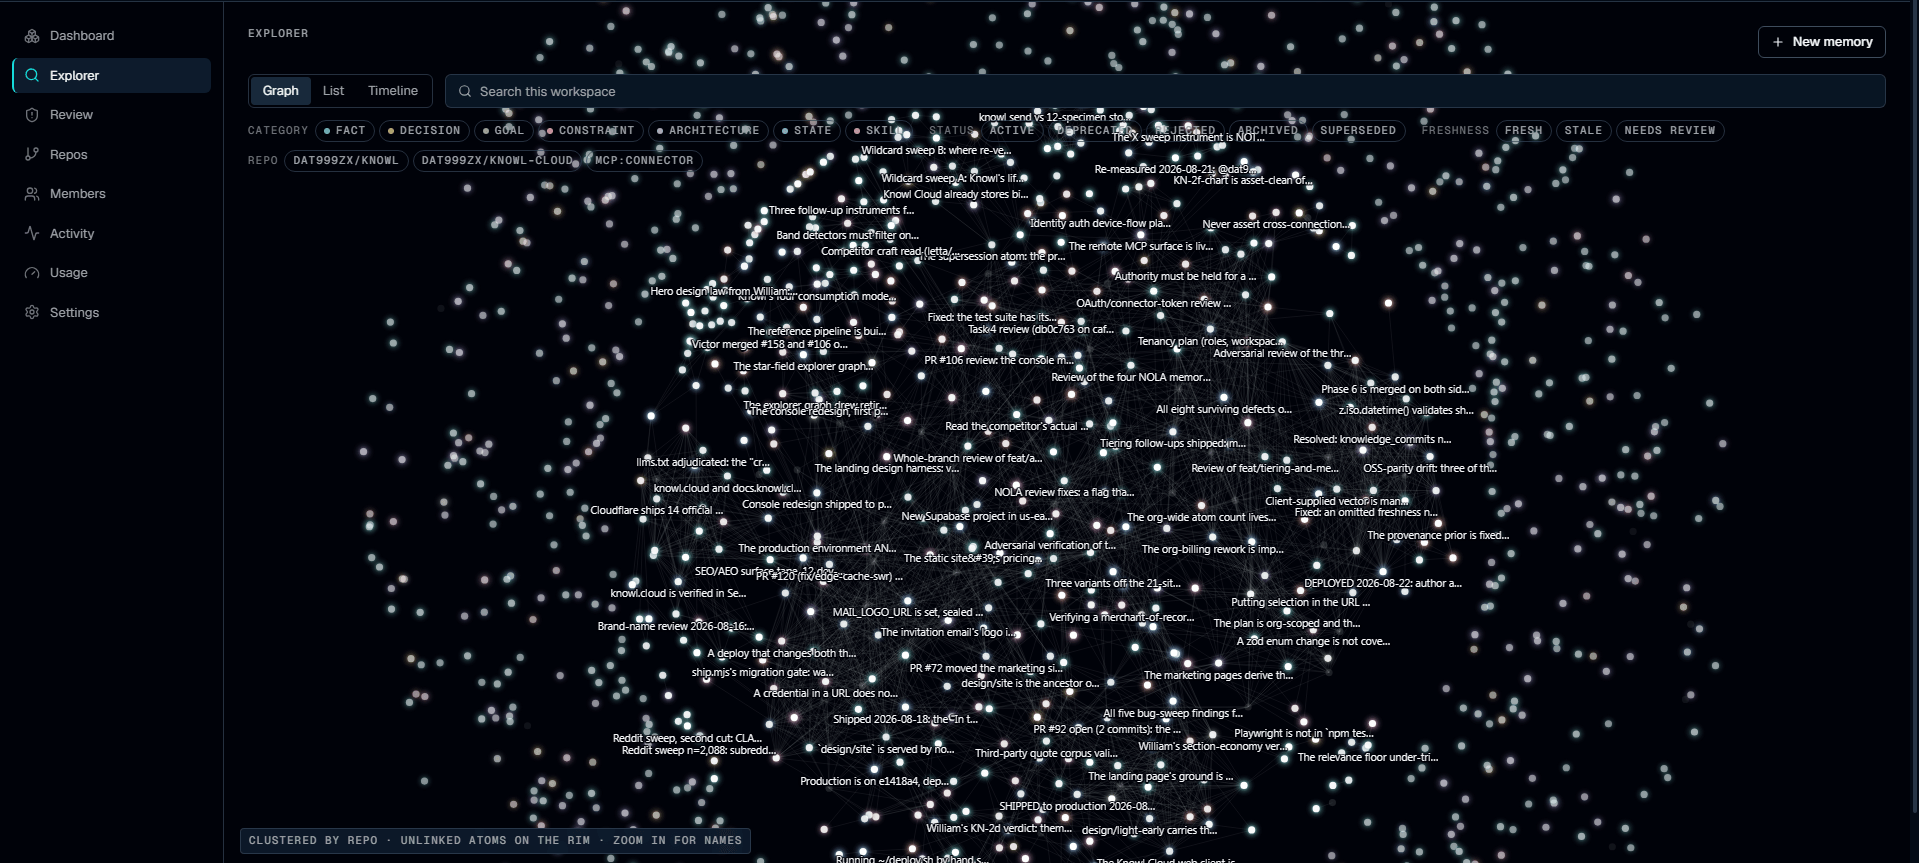
Everything above is local and needs no account. knowl.cloud is the optional hosted layer for when one machine is not enough:
- Shared workspaces. Knowledge written in one checkout reaches teammates' agents, with each repository still owning what it publishes.
- Browser agents. claude.ai and chatgpt.com cannot run a local process, so they connect over a remote MCP endpoint with a token scoped to one workspace.
Local-only remains a first-class way to run Knowl. Nothing here is required to use anything above.
What gets stored
Every atom has exactly one of seven categories:
| Category | Use it for |
|---|---|
fact |
Stable project truths, conventions, and verified behavior |
decision |
A selected option with reasoning and alternatives |
goal |
An intended outcome that guides future work |
constraint |
A rule or boundary that must continue to hold |
architecture |
How components are arranged and interact |
state |
Current progress, readiness, blockers, or operational status |
skill |
A reusable procedure or learned workflow description |
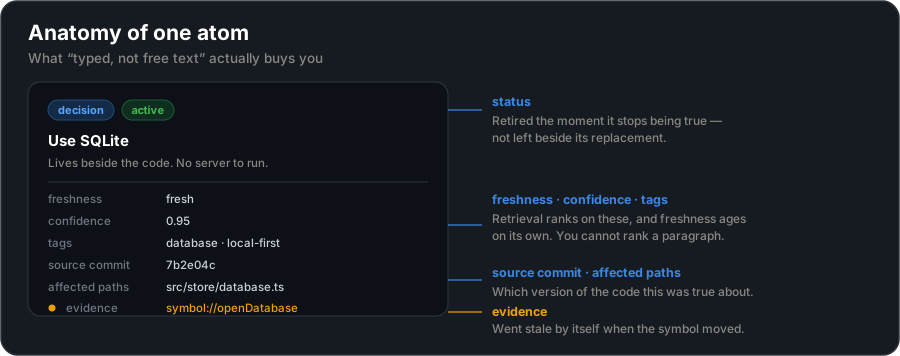
Alongside the content, each atom keeps a status (active, deprecated, rejected, archived,
superseded), a freshness flag, confidence, tags, source commit, affected paths, and optional
evidence pointing at files, commits, tests, commands, URLs, or indexed code symbols. File and
symbol evidence go stale on their own when the code moves, which is how an atom admits it may be
out of date instead of asserting a version of the repository that no longer exists.
What Knowl de